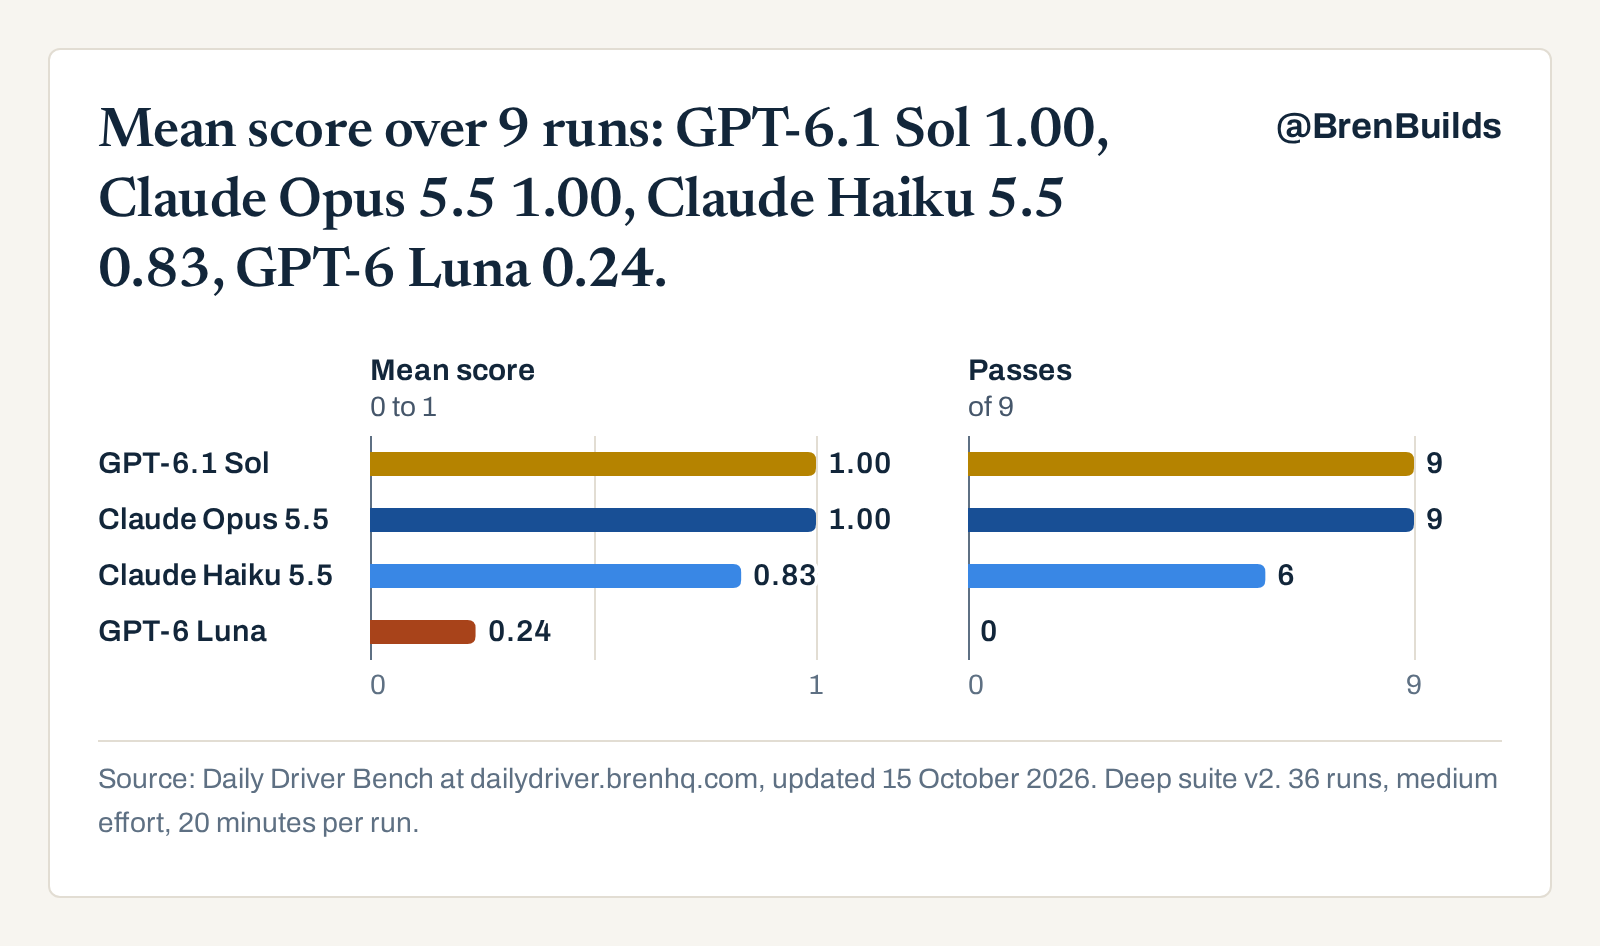
GPT-6.1 Sol and Claude Opus 5.5 passed every run; Claude Haiku 5.5 passed 6 of 9 and GPT-6 Luna none.
Each model got 3 runs at each of 3 areas of work in one real app, 20 minutes per run, each run scored from 0 to 1. GPT-6.1 Sol was about 1.7 times as fast as Claude Opus 5.5 by median minutes per passing run, and Claude Opus 5.5's estimated cost per pass was 3.2 to 3.5 times GPT-6.1 Sol's at list prices.
Each version tests something different. Scores don't carry over.
Results#
Mean score over 9 runs: GPT-6.1 Sol 1.00, Claude Opus 5.5 1.00, Claude Haiku 5.5 0.83, GPT-6 Luna 0.24.
3 areas, 3 runs each. A run passes when it meets its area's bar, shown under Each area. Two models passed every run, so these scores can't tell their ability apart on this suite, only their time and cost. Tap or hover over a bar to see each area.
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 15 October 2026. Deep suite v2. 36 runs, medium effort, 20 minutes per run.
Each area#
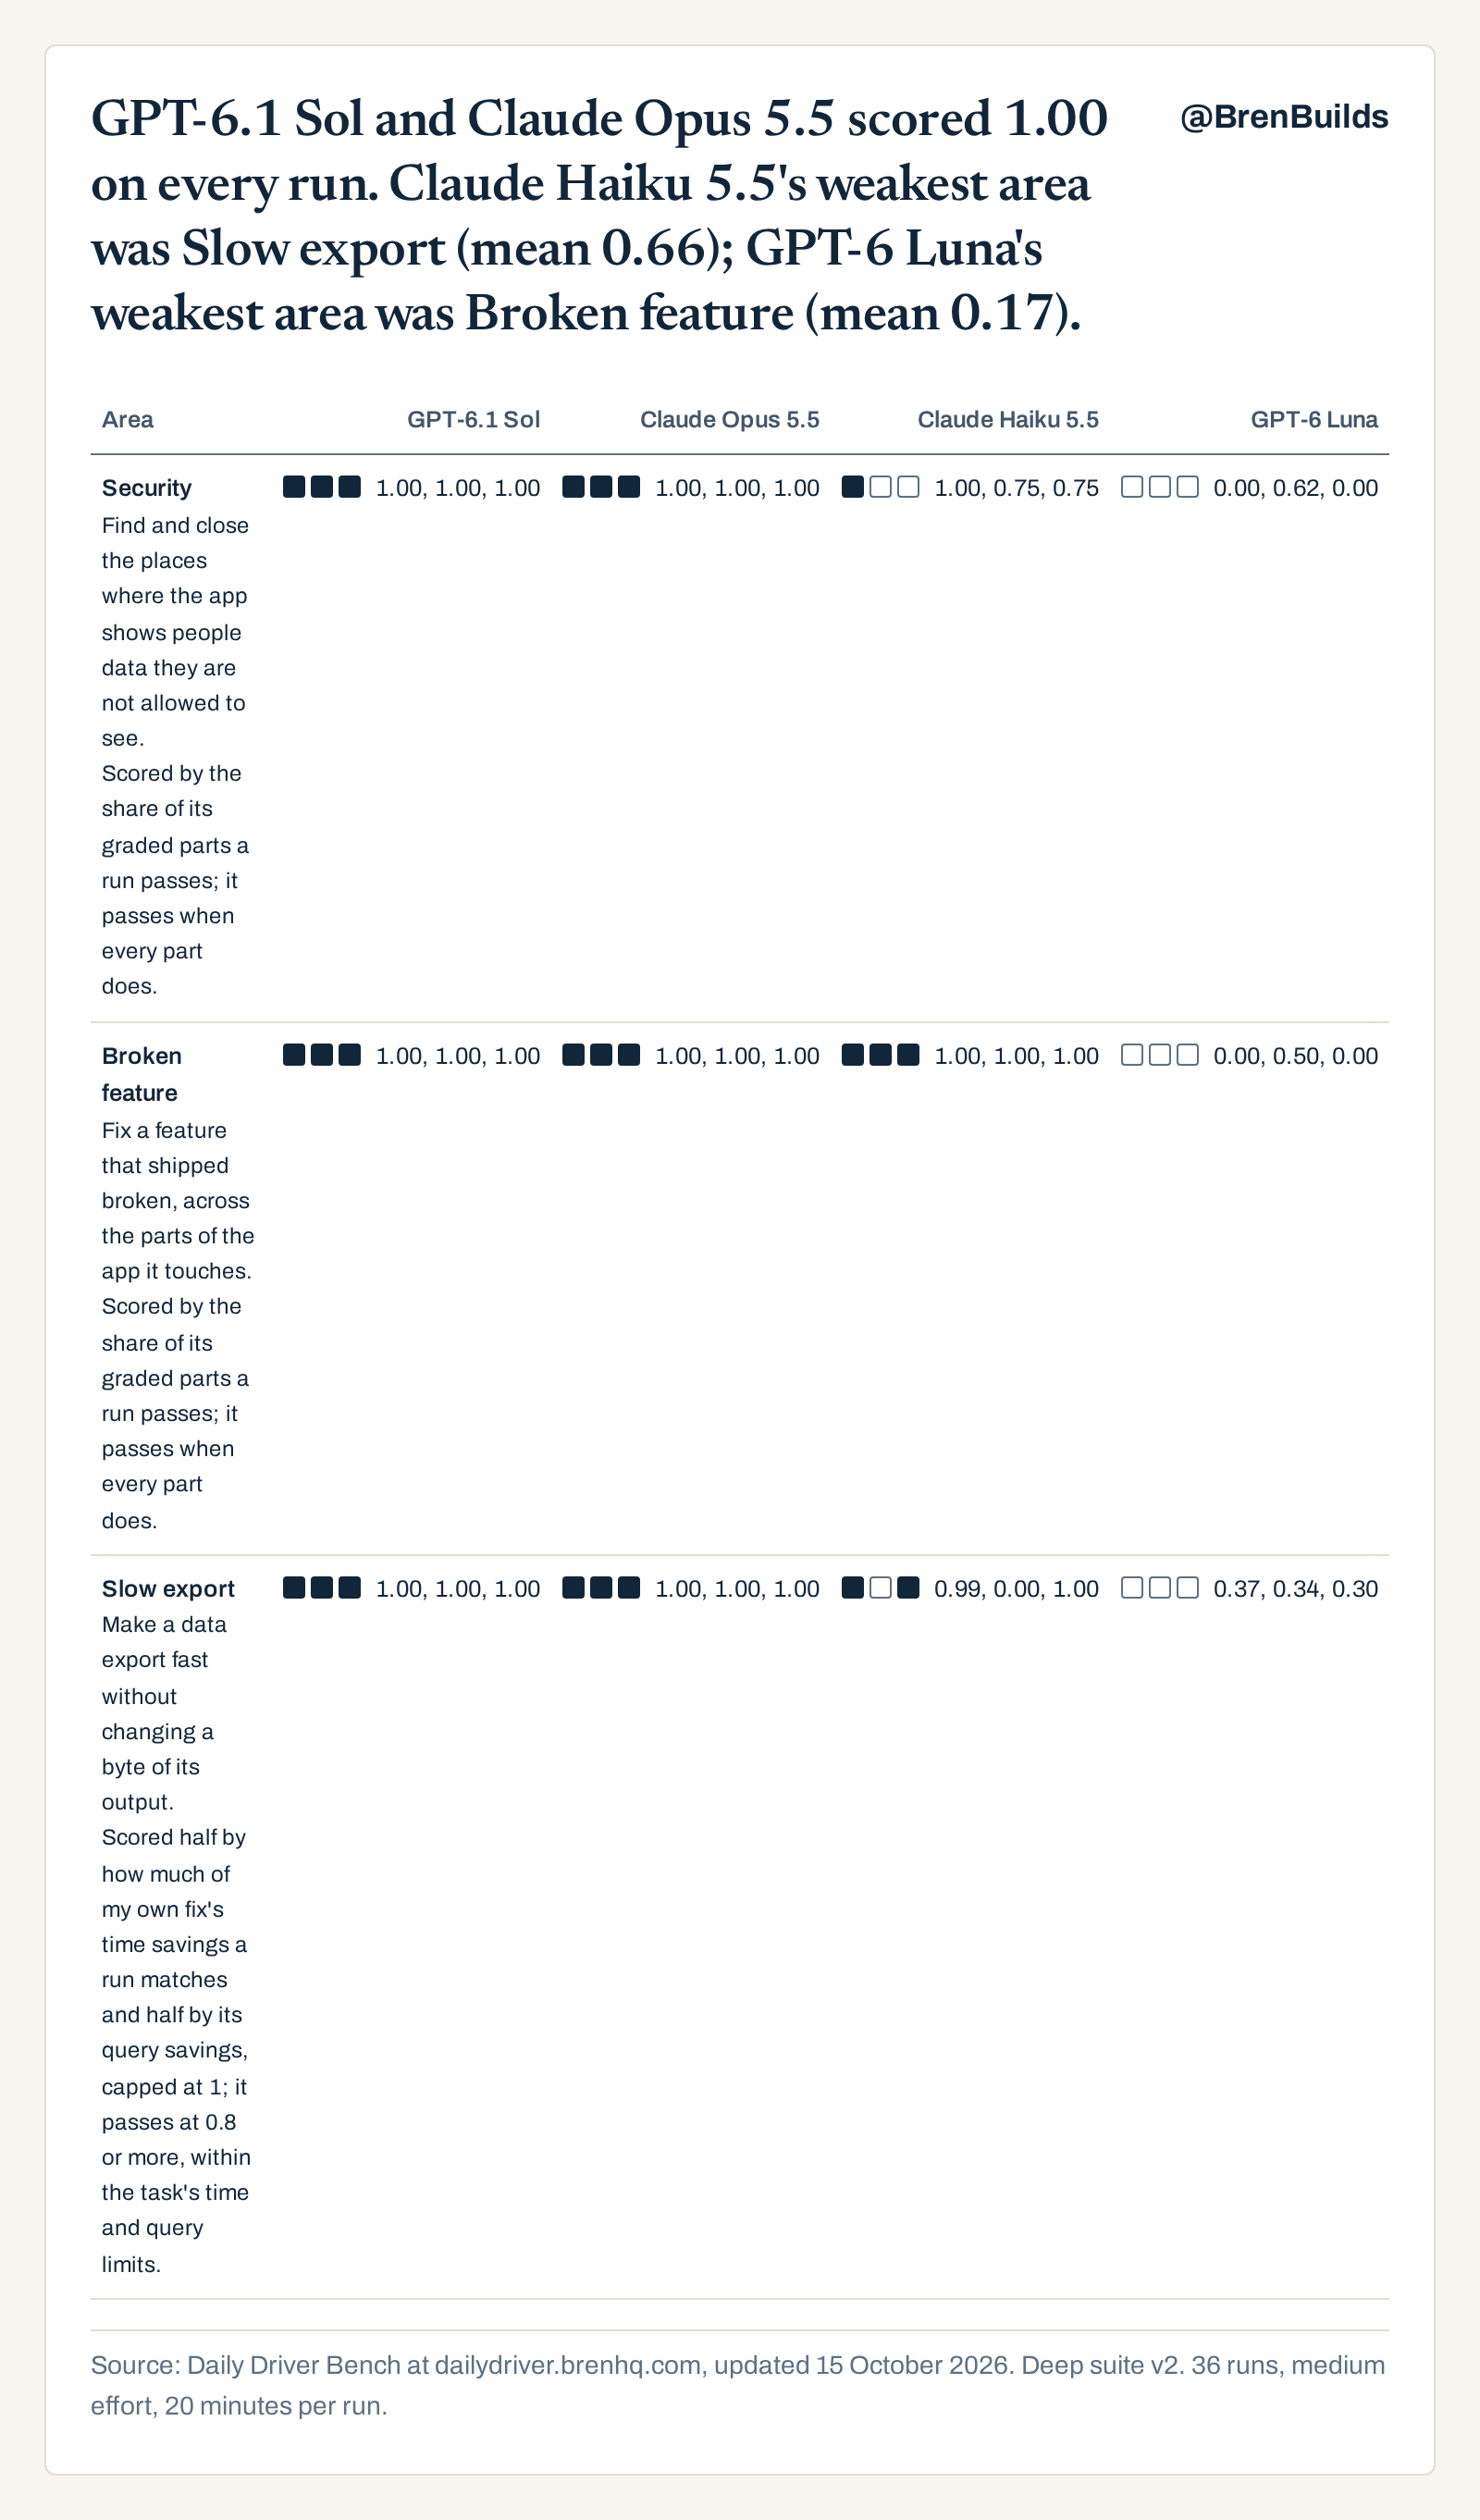
GPT-6.1 Sol and Claude Opus 5.5 scored 1.00 on every run. Claude Haiku 5.5's weakest area was Slow export (mean 0.66); GPT-6 Luna's weakest area was Broken feature (mean 0.17).
Each square is one run; filled means it passed. The numbers are each run's score; narrow screens show their mean.
| Area | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| SecurityFind and close the places where the app shows people data they are not allowed to see. | 1.00, 1.00, 1.00 | 1.00, 1.00, 1.00 | 1.00, 0.75, 0.75 | 0.00, 0.62, 0.00 |
| Broken featureFix a feature that shipped broken, across the parts of the app it touches. | 1.00, 1.00, 1.00 | 1.00, 1.00, 1.00 | 1.00, 1.00, 1.00 | 0.00, 0.50, 0.00 |
| Slow exportMake a data export fast without changing a byte of its output. | 1.00, 1.00, 1.00 | 1.00, 1.00, 1.00 | 0.99, 0.00, 1.00 | 0.37, 0.34, 0.30 |
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 15 October 2026. Deep suite v2. 36 runs, medium effort, 20 minutes per run.
Time#
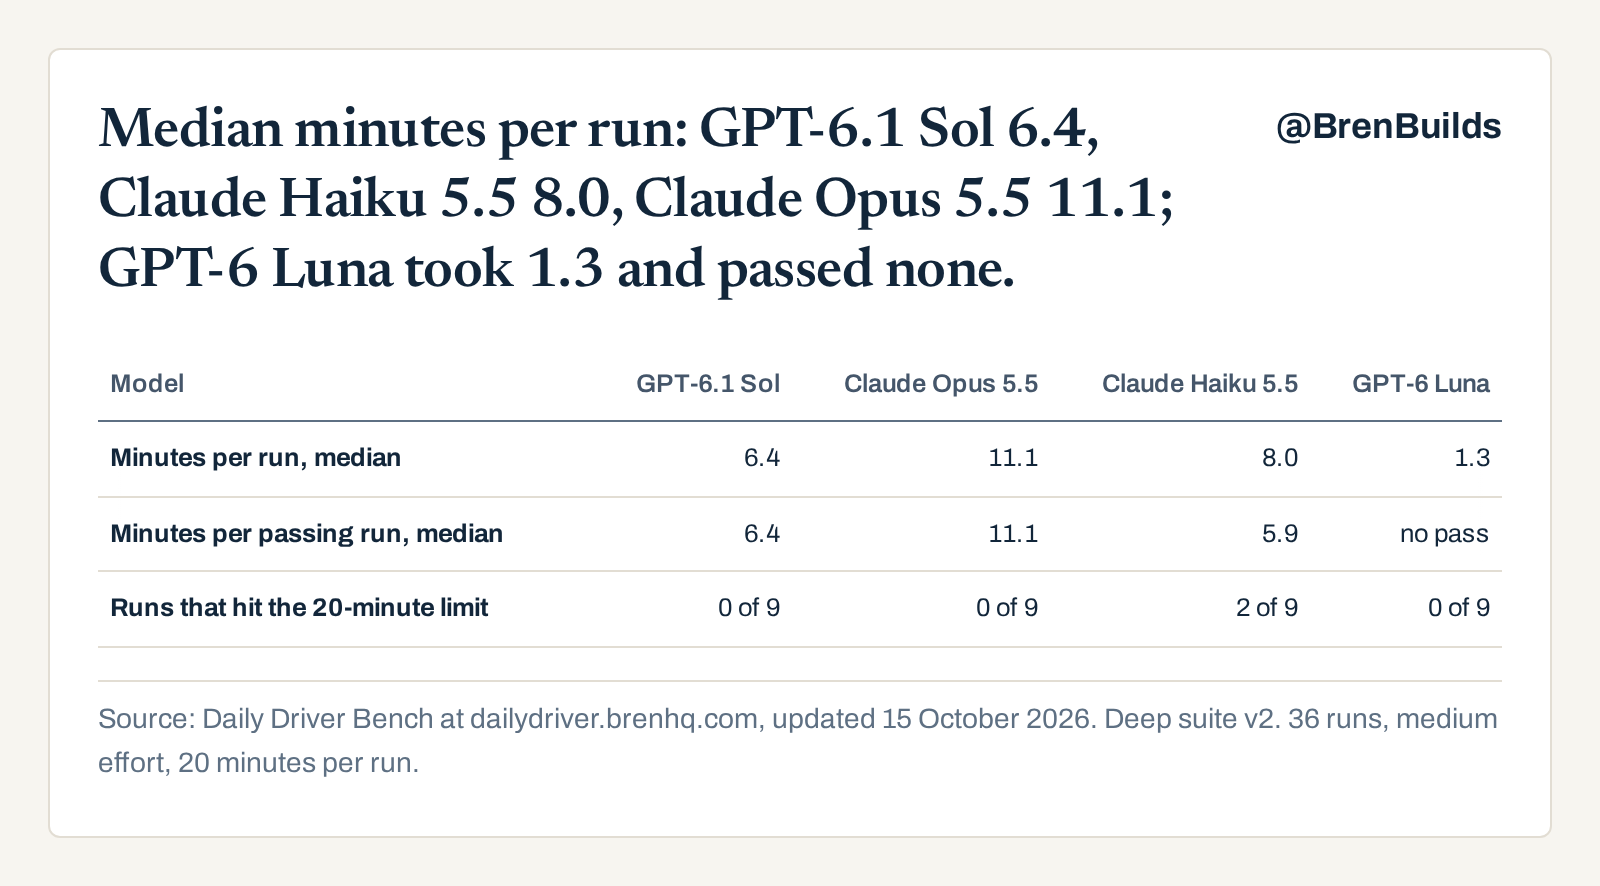
Median minutes per run: GPT-6.1 Sol 6.4, Claude Haiku 5.5 8.0, Claude Opus 5.5 11.1; GPT-6 Luna took 1.3 and passed none.
Minutes from start to finish, checks included. Minutes per passing run counts only the runs a model passed, and those differ by model.
| Model | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Minutes per run, median | 6.4 | 11.1 | 8.0 | 1.3 |
| Minutes per passing run, median | 6.4 | 11.1 | 5.9 | no pass |
| Runs that hit the 20-minute limit | 0 of 9 | 0 of 9 | 2 of 9 | 0 of 9 |
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 15 October 2026. Deep suite v2. 36 runs, medium effort, 20 minutes per run.
Cost#
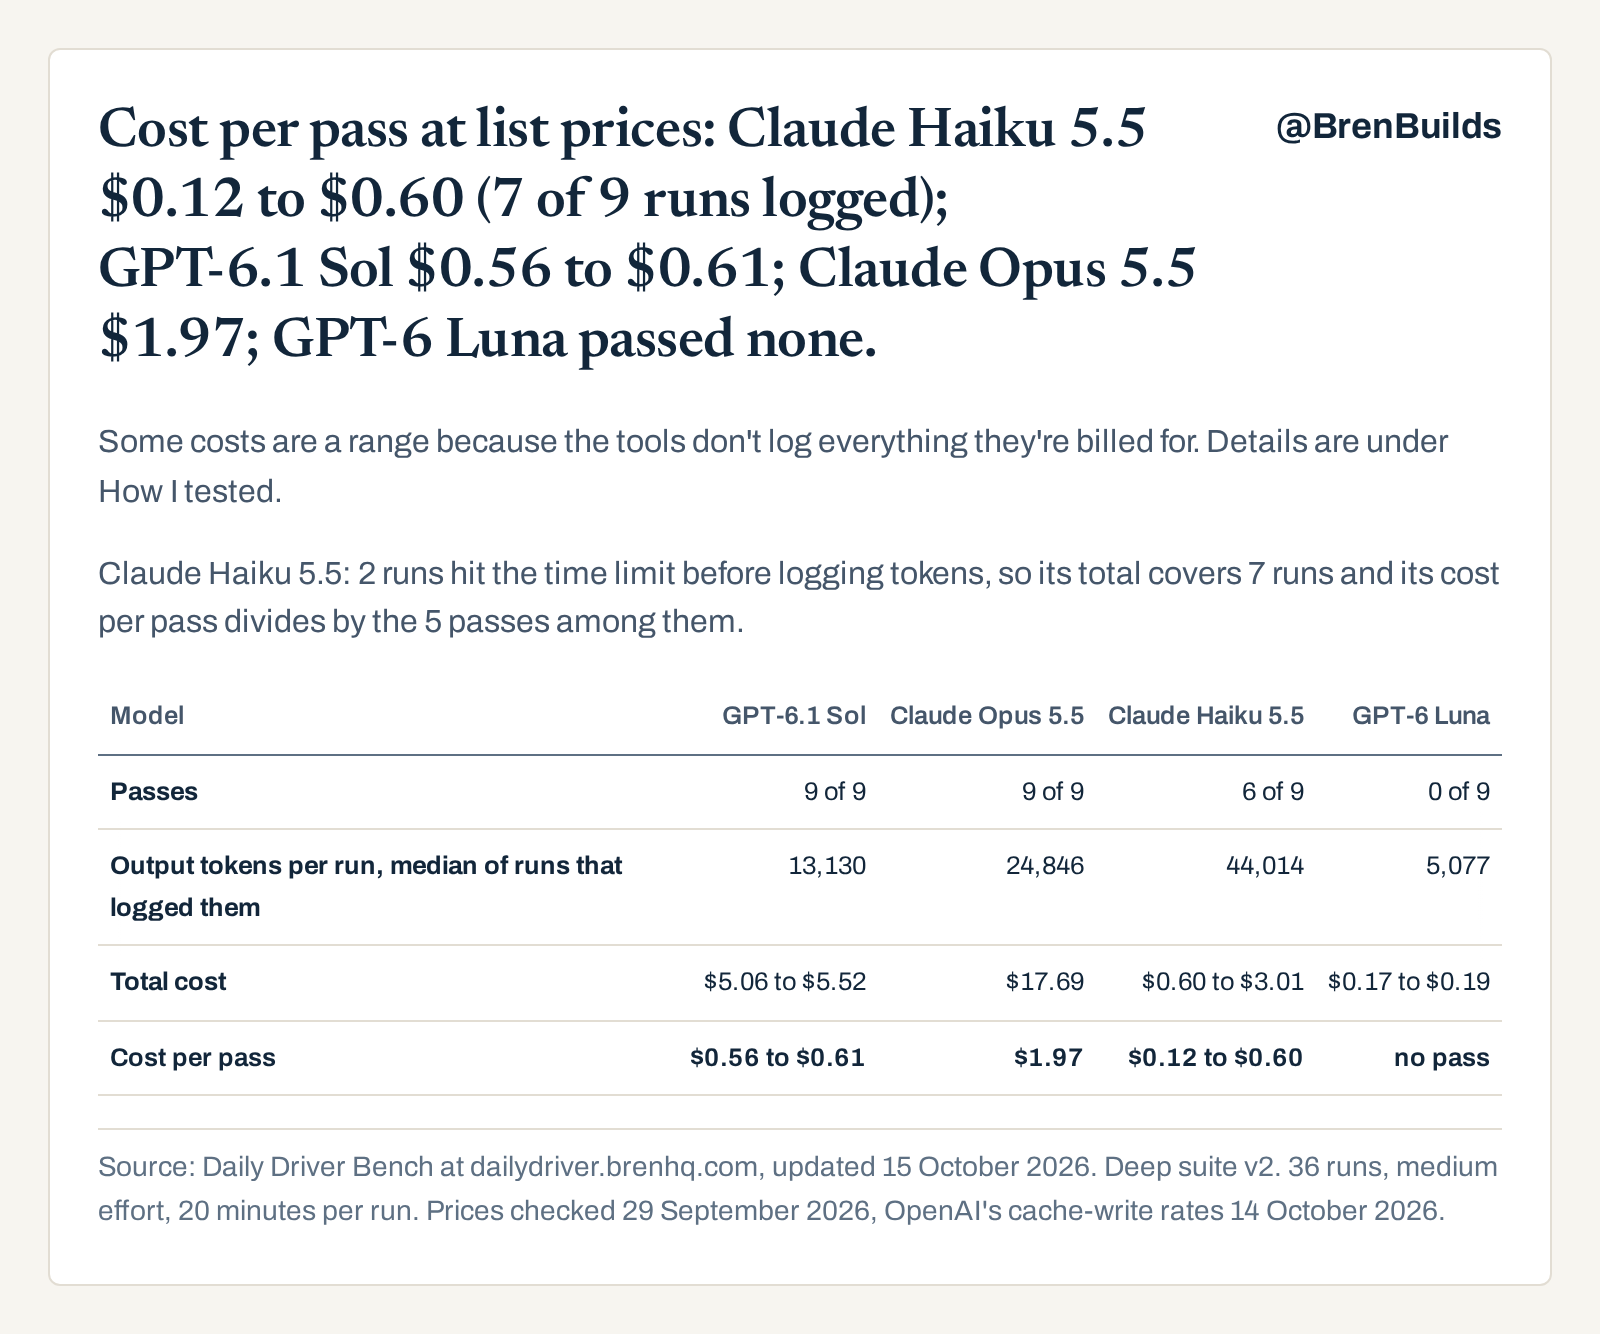
Cost per pass at list prices: Claude Haiku 5.5 $0.12 to $0.60 (7 of 9 runs logged); GPT-6.1 Sol $0.56 to $0.61; Claude Opus 5.5 $1.97; GPT-6 Luna passed none.
An estimate at each vendor's list prices: the cost of every run that logged its tokens, failed ones included, divided by the passes among them.
Some costs are a range because the tools don't log everything they're billed for. Details are under How I tested.
Claude Haiku 5.5: 2 runs hit the time limit before logging tokens, so its total covers 7 runs and its cost per pass divides by the 5 passes among them.
| Model | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Passes | 9 of 9 | 9 of 9 | 6 of 9 | 0 of 9 |
| Output tokens per run, median of runs that logged them | 13,130 | 24,846 | 44,014 | 5,077 |
| Total cost | $5.06 to $5.52 | $17.69 | $0.60 to $3.01 | $0.17 to $0.19 |
| Cost per pass | $0.56 to $0.61 | $1.97 | $0.12 to $0.60 | no pass |
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 15 October 2026. Deep suite v2. 36 runs, medium effort, 20 minutes per run. Prices checked 29 September 2026, OpenAI's cache-write rates 14 October 2026.
How I tested#
How the tasks were made, run and graded
Version 1 used tasks from public task sets. For version 2 I wrote my own tasks in one real open-source web app: an audit for data people shouldn't see, a feature that shipped broken, and a data export that has to get fast without changing its output. Each task has hidden checks the model never sees. Security and Broken feature score a run by the share of their graded parts it passes, and a run passes when every part does. Slow export scores a run half by how much of my own fix's time savings it matches and half by its query savings, capped at 1, and a run passes at 0.8 or more within the task's time and query limits. A run that breaks any of the app's own tests scores 0. Tasks, prompts and graders are private so later runs stay fair.
Before counted runs began, each task was checked the same way: my own fix scores 1, the untouched code scores 0, and the tested wrong fixes scored below 1. Three outside reviewers (GPT-6 Astra, Grok 4.7 and Gemini 4 Argon) checked every task for fairness, and I made the tasks harder twice after trial rounds where too many runs passed. The trial rounds aren't counted.
This is version 2, frozen 15 October 2026: 3 areas, 3 runs each, the same settings and the same containers. Each version tests something different, so scores don't carry over from version 1.
Claude Opus 5.5 and Claude Haiku 5.5 ran in Claude Code 2.1.284, and GPT-6.1 Sol and GPT-6 Luna in Codex CLI 0.159.0, all at medium effort, 20 minutes per run (2 runs hit the limit and were graded on the code at that point). Each run ran in its own container with no internet except the model's API. Its change was then copied into a fresh container and graded there, after the app's own tests were put back. The two tools ran side by side; the export task, which measures time, was graded afterwards one run at a time with nothing else running.
Costs are estimates at each vendor's standard list prices, from the tokens each run logged. Claude Haiku 5.5 is a range because Anthropic charges more for prompts over 100k tokens and prompt sizes weren't logged; GPT costs are a range because Codex doesn't log cache writes, which OpenAI bills at 1.25 times the input price. 2 runs stopped at the time limit before logging tokens, so they have no cost estimate and aren't in the totals. The runs ran on subscriptions, so these are not what was spent.
Limits: 3 areas and 3 runs each, one app, one tool and one effort setting per model. Two models passed every run, so these scores can't tell their ability apart on this suite, only which was faster and cheaper here.
Every run's area, score, time and cost is in results.json, under deep_v2_runs and deep_v2_suite.