Claude Opus 5.5 had the best average on the speed-up and schedule tasks, GPT-6.1 Sol on the forecast task. Both averaged 0.98 or more on every correctness task.
Four models got two runs at each of six tasks in six languages, 20 minutes per run (10 for the job service). The three open-ended tasks split the leaders. On the three correctness tasks, GPT-6.1 Sol and Claude Opus 5.5 were within 0.02 of each other. Both of Claude Haiku 5.5's runs on the web app feature were invalid. GPT-6 Luna's means ranged from 0.05 to 0.54. GPT-6.1 Sol's median run took 11.3 minutes to Claude Opus 5.5's 20.1 (Opus hit the time limit on 9 of 12 runs), and Opus's estimated cost per run was 3.8 to 4.1 times Sol's at list prices.
Each version tests something different. Scores don't carry over.
Score by cost#
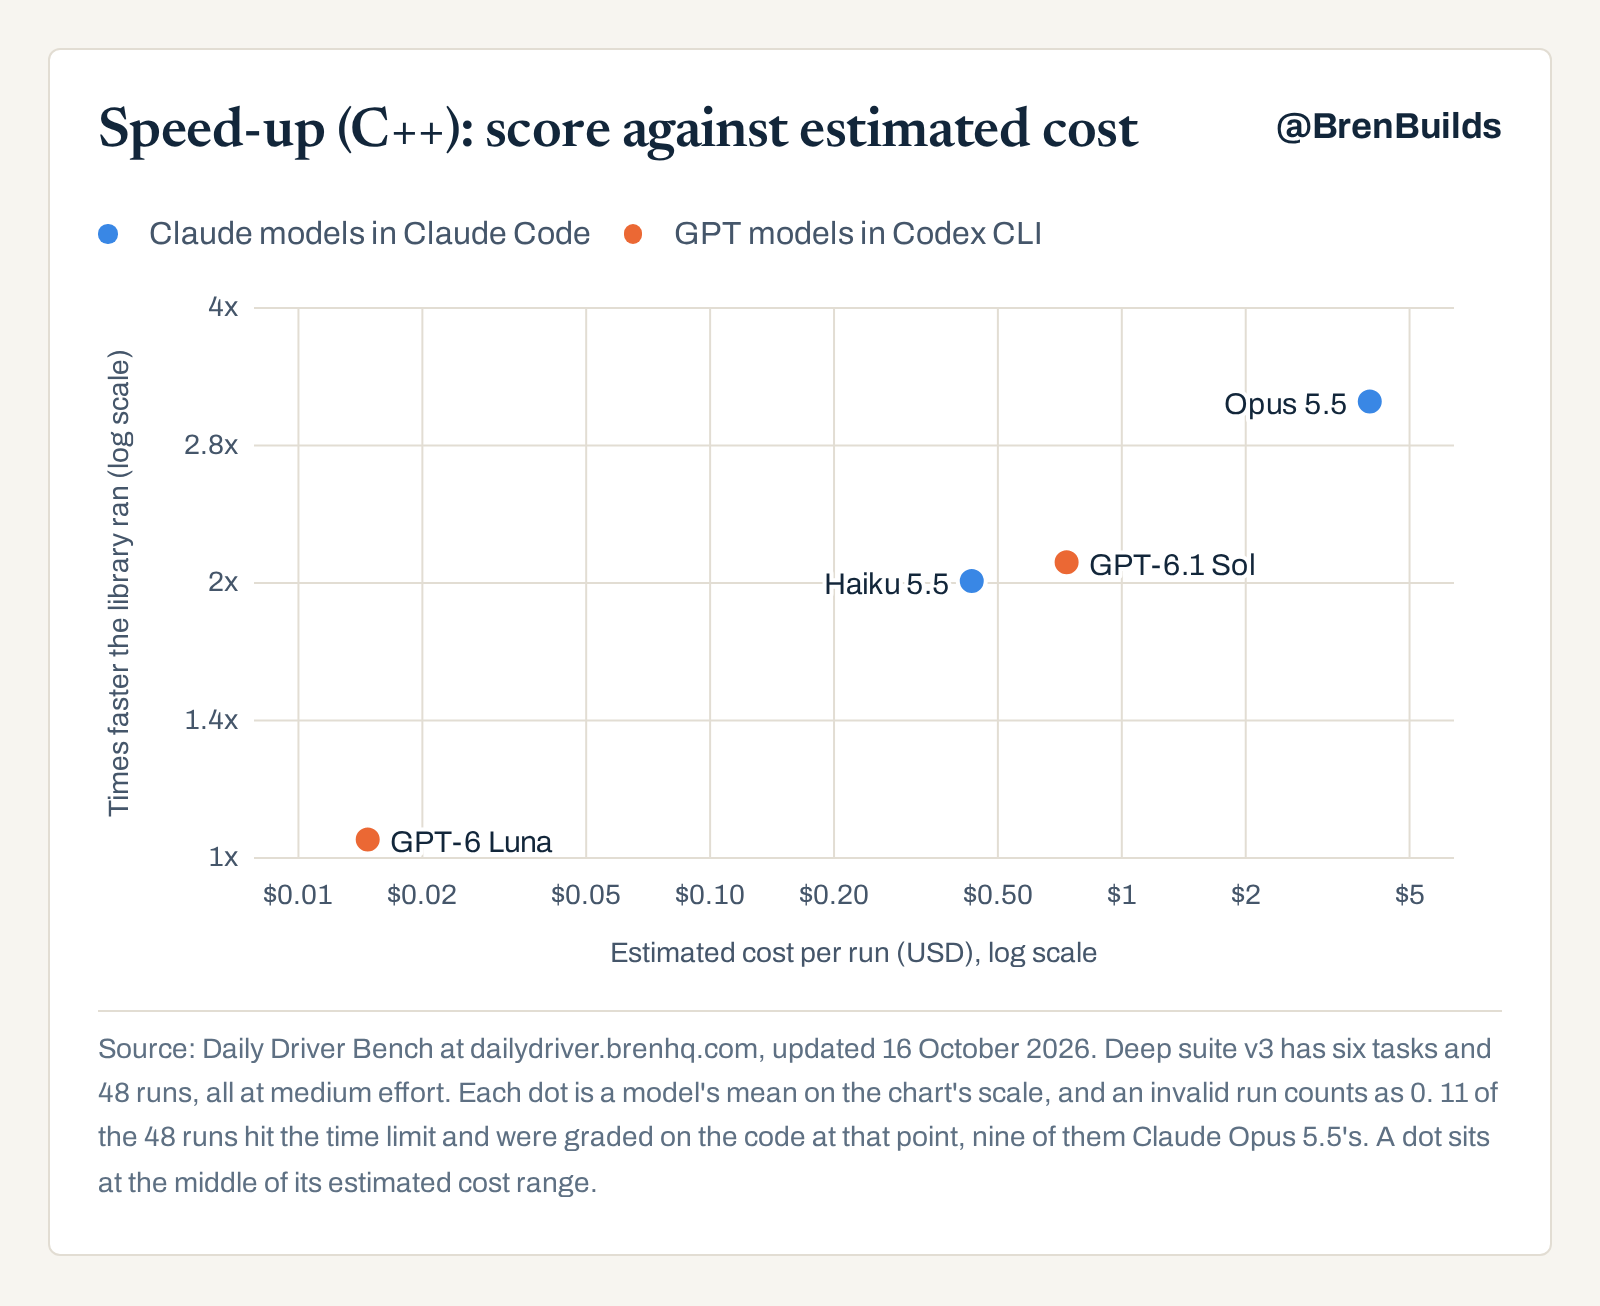
Speed-up (C++): score against estimated cost
Two runs per model. Higher is better, and left is cheaper.
- Claude models in Claude Code
- GPT models in Codex CLI
Show as a table
| Model | Score | Cost per run | Output tokens | Minutes | Frontier |
|---|---|---|---|---|---|
| GPT-6 Luna | 0.07 | $0.014 to $0.016 | 2,948 | 1.2 | on it |
| Claude Haiku 5.5 | 1.01 | $0.14 to $0.72 | 107,036 | 14.4 | on it |
| GPT-6.1 Sol | 1.08 | $0.71 to $0.76 | 27,653 | 11.0 | on it |
| Claude Opus 5.5 | 1.66 | $4.00 | 89,104 | 20.1 | on it |
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 16 October 2026. Deep suite v3 has six tasks and 48 runs, all at medium effort. Each dot is a model's mean on the chart's scale, and an invalid run counts as 0. 11 of the 48 runs hit the time limit and were graded on the code at that point, nine of them Claude Opus 5.5's. A dot sits at the middle of its estimated cost range.
Open-ended tasks#
These measure how much a run improved on where the code started, on a log2 scale, and aren't capped at my own fix's score.
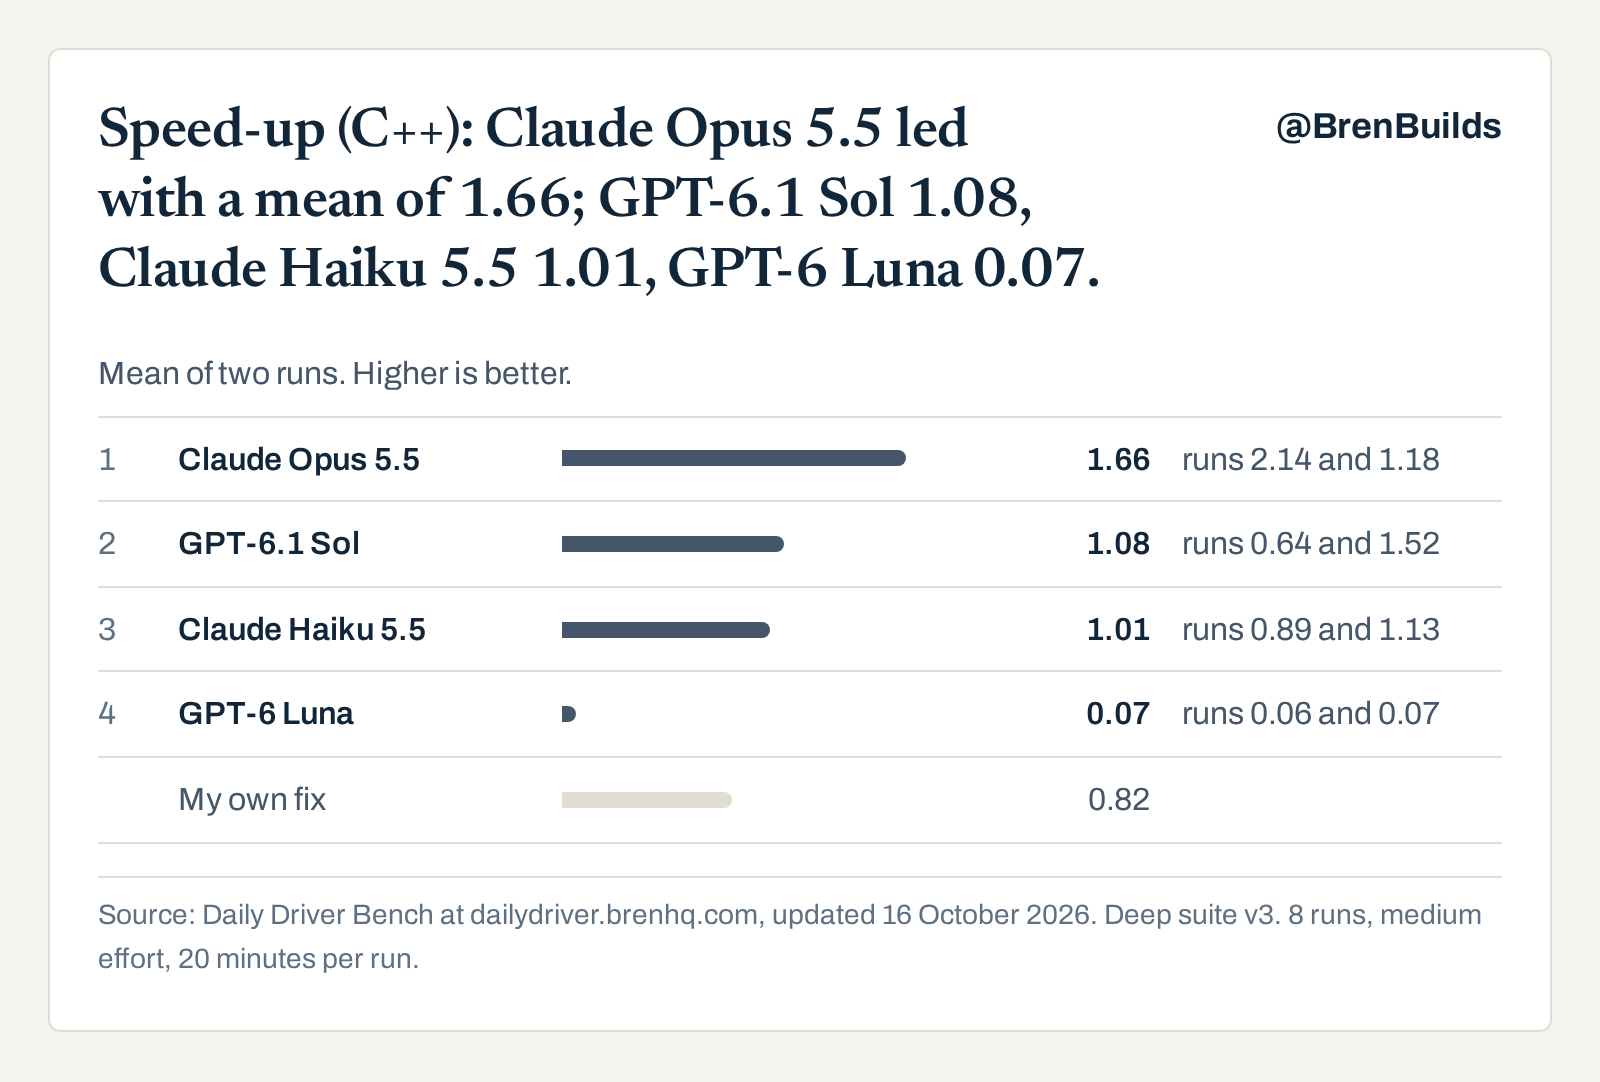
Speed-up (C++): Claude Opus 5.5 led with a mean of 1.66; GPT-6.1 Sol 1.08, Claude Haiku 5.5 1.01, GPT-6 Luna 0.07.
Make a released open-source library faster without changing its output. Times faster on a log2 scale, averaged over hidden workloads: 1 is twice as fast, 2 is four times. My own fix scored 0.82, the gray row.
Mean of two runs. Higher is better.
- 1Claude Opus 5.51.66runs 2.14 and 1.18
- 2GPT-6.1 Sol1.08runs 0.64 and 1.52
- 3Claude Haiku 5.51.01runs 0.89 and 1.13
- 4GPT-6 Luna0.07runs 0.06 and 0.07
- My own fix0.82
Each run, and the mean at 10 minutes
The code was saved at 10 minutes without stopping the model. A run that finished before then keeps its final score there.
| Score | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Run 1 | 0.64 | 2.14 | 0.89 | 0.06 |
| Run 2 | 1.52 | 1.18 | 1.13 | 0.07 |
| Mean | 1.08 | 1.66 | 1.01 | 0.07 |
| At 10 minutes, mean | 1.06 | 1.06 | 0.98 | 0.07 |
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 16 October 2026. Deep suite v3. 8 runs, medium effort, 20 minutes per run.
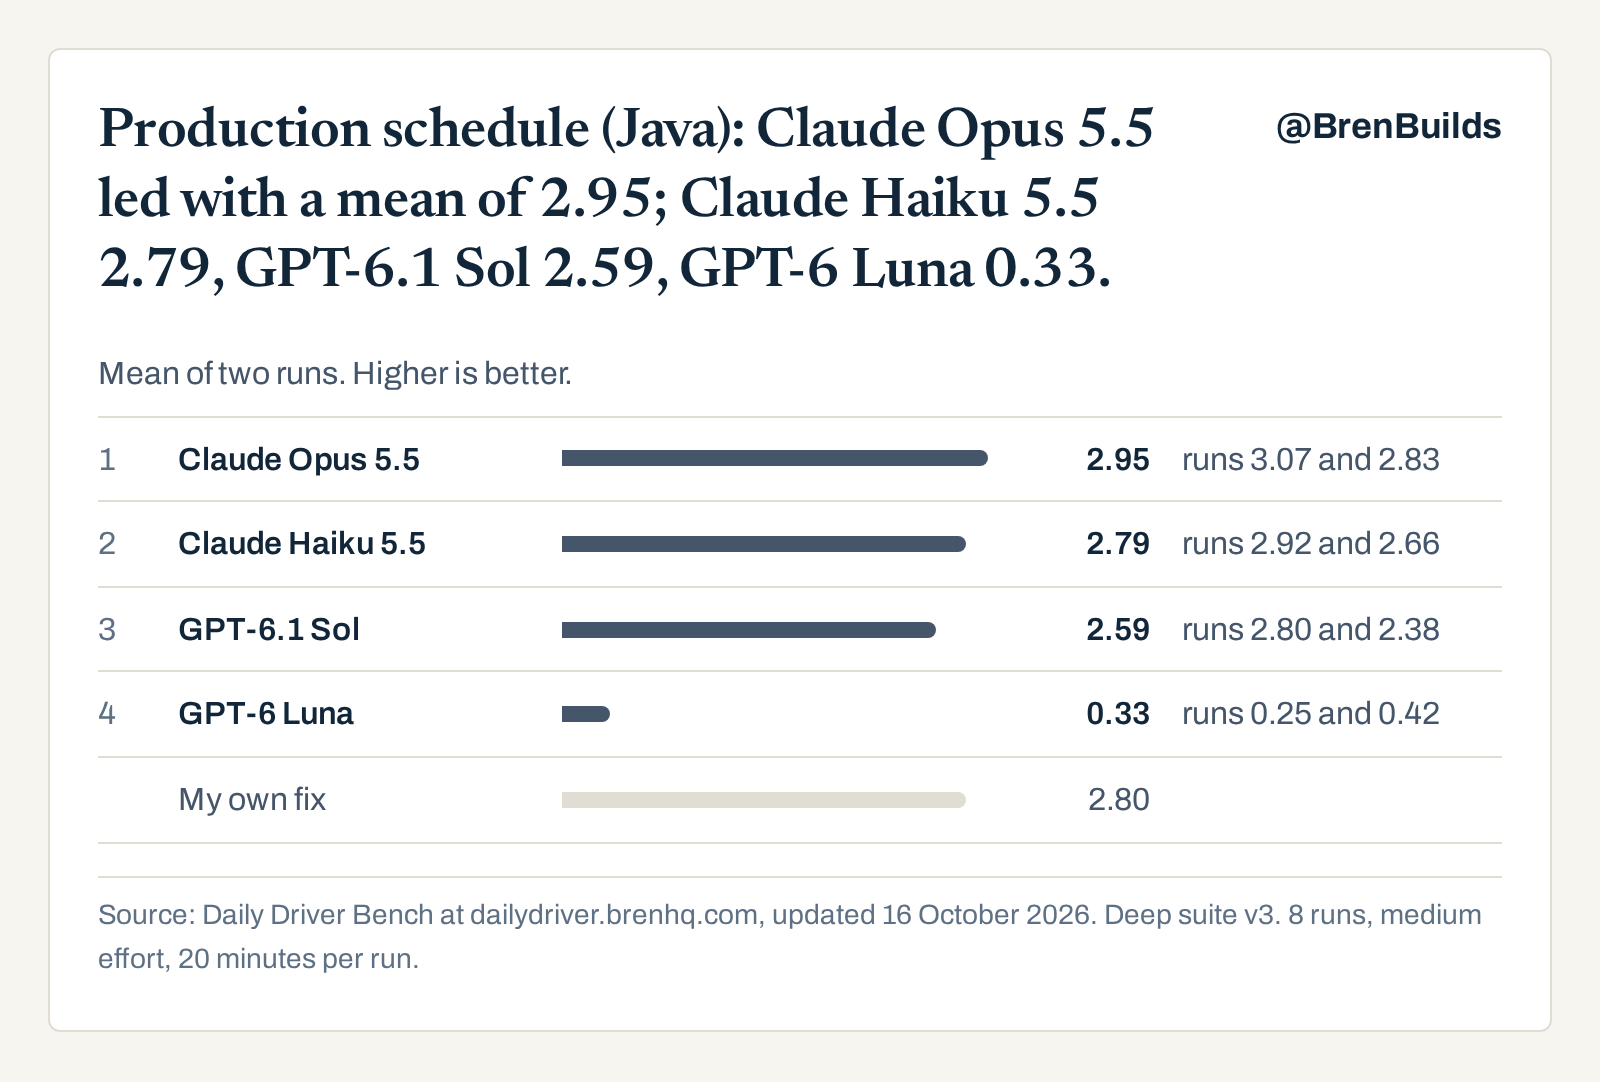
Production schedule (Java): Claude Opus 5.5 led with a mean of 2.95; Claude Haiku 5.5 2.79, GPT-6.1 Sol 2.59, GPT-6 Luna 0.33.
Make my own production planner's schedules less late, keeping every rule. How much lateness shrank against the current planner, log2, averaged over hidden cases: 1 is about half the lateness. My own fix scored 2.80, the gray row.
Mean of two runs. Higher is better.
- 1Claude Opus 5.52.95runs 3.07 and 2.83
- 2Claude Haiku 5.52.79runs 2.92 and 2.66
- 3GPT-6.1 Sol2.59runs 2.80 and 2.38
- 4GPT-6 Luna0.33runs 0.25 and 0.42
- My own fix2.80
Each run, and the mean at 10 minutes
The code was saved at 10 minutes without stopping the model. A run that finished before then keeps its final score there.
| Score | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Run 1 | 2.80 | 3.07 | 2.92 | 0.25 |
| Run 2 | 2.38 | 2.83 | 2.66 | 0.42 |
| Mean | 2.59 | 2.95 | 2.79 | 0.33 |
| At 10 minutes, mean | 2.61 | 2.94 | 2.79 | 0.33 |
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 16 October 2026. Deep suite v3. 8 runs, medium effort, 20 minutes per run.
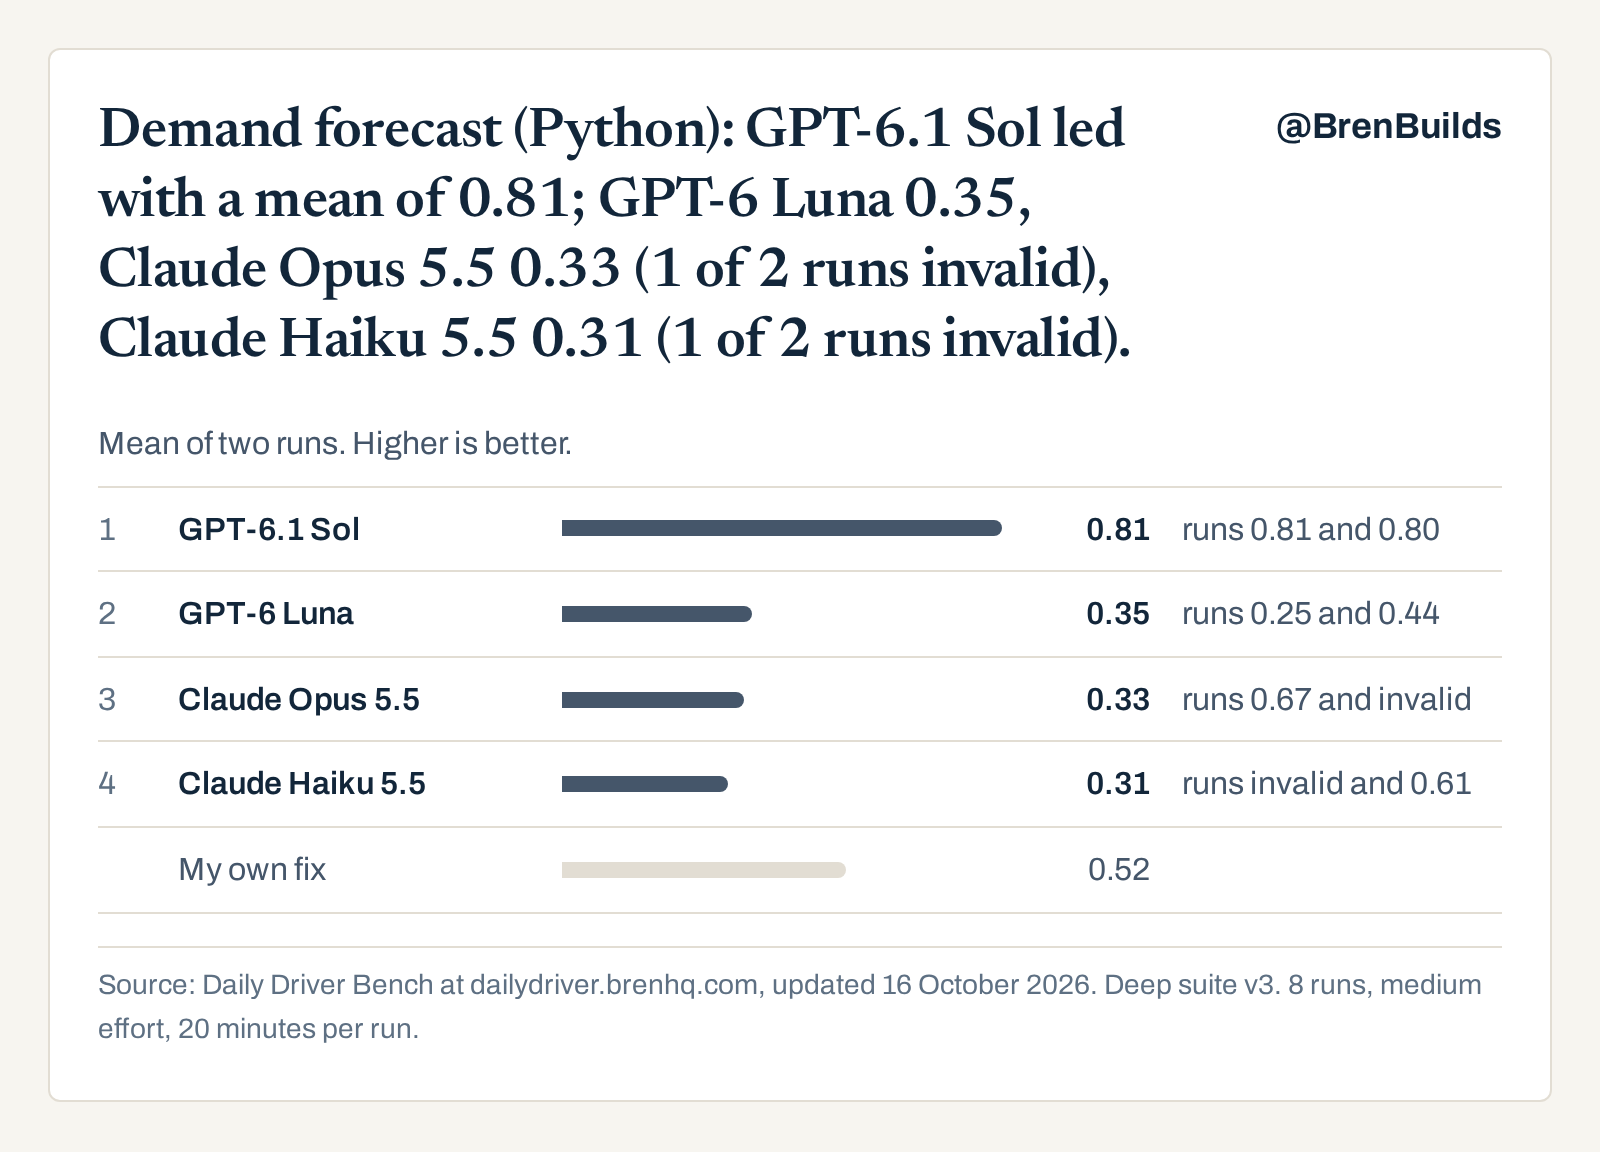
Demand forecast (Python): GPT-6.1 Sol led with a mean of 0.81; GPT-6 Luna 0.35, Claude Opus 5.5 0.33 (1 of 2 runs invalid), Claude Haiku 5.5 0.31 (1 of 2 runs invalid).
Forecast daily demand in my own app more accurately than its simple baseline. How much the forecast error shrank against the baseline, log2, averaged over hidden periods: 1 is about half the error. My own fix scored 0.52, the gray row. An invalid run's code didn't build or broke the project's own tests; it counts as 0 in the mean.
Mean of two runs. Higher is better.
- 1GPT-6.1 Sol0.81runs 0.81 and 0.80
- 2GPT-6 Luna0.35runs 0.25 and 0.44
- 3Claude Opus 5.50.33runs 0.67 and invalid
- 4Claude Haiku 5.50.31runs invalid and 0.61
- My own fix0.52
Each run, and the mean at 10 minutes
The code was saved at 10 minutes without stopping the model. A run that finished before then keeps its final score there.
| Score | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Run 1 | 0.81 | 0.67 | invalid | 0.25 |
| Run 2 | 0.80 | invalid | 0.61 | 0.44 |
| Mean | 0.81 | 0.33 | 0.31 | 0.35 |
| At 10 minutes, mean | 0.81 | 0.27 | 0.00 | 0.35 |
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 16 October 2026. Deep suite v3. 8 runs, medium effort, 20 minutes per run.
Correctness tasks#
These score the share of hidden checks, or hidden files, a run got right, from 0 to 1.
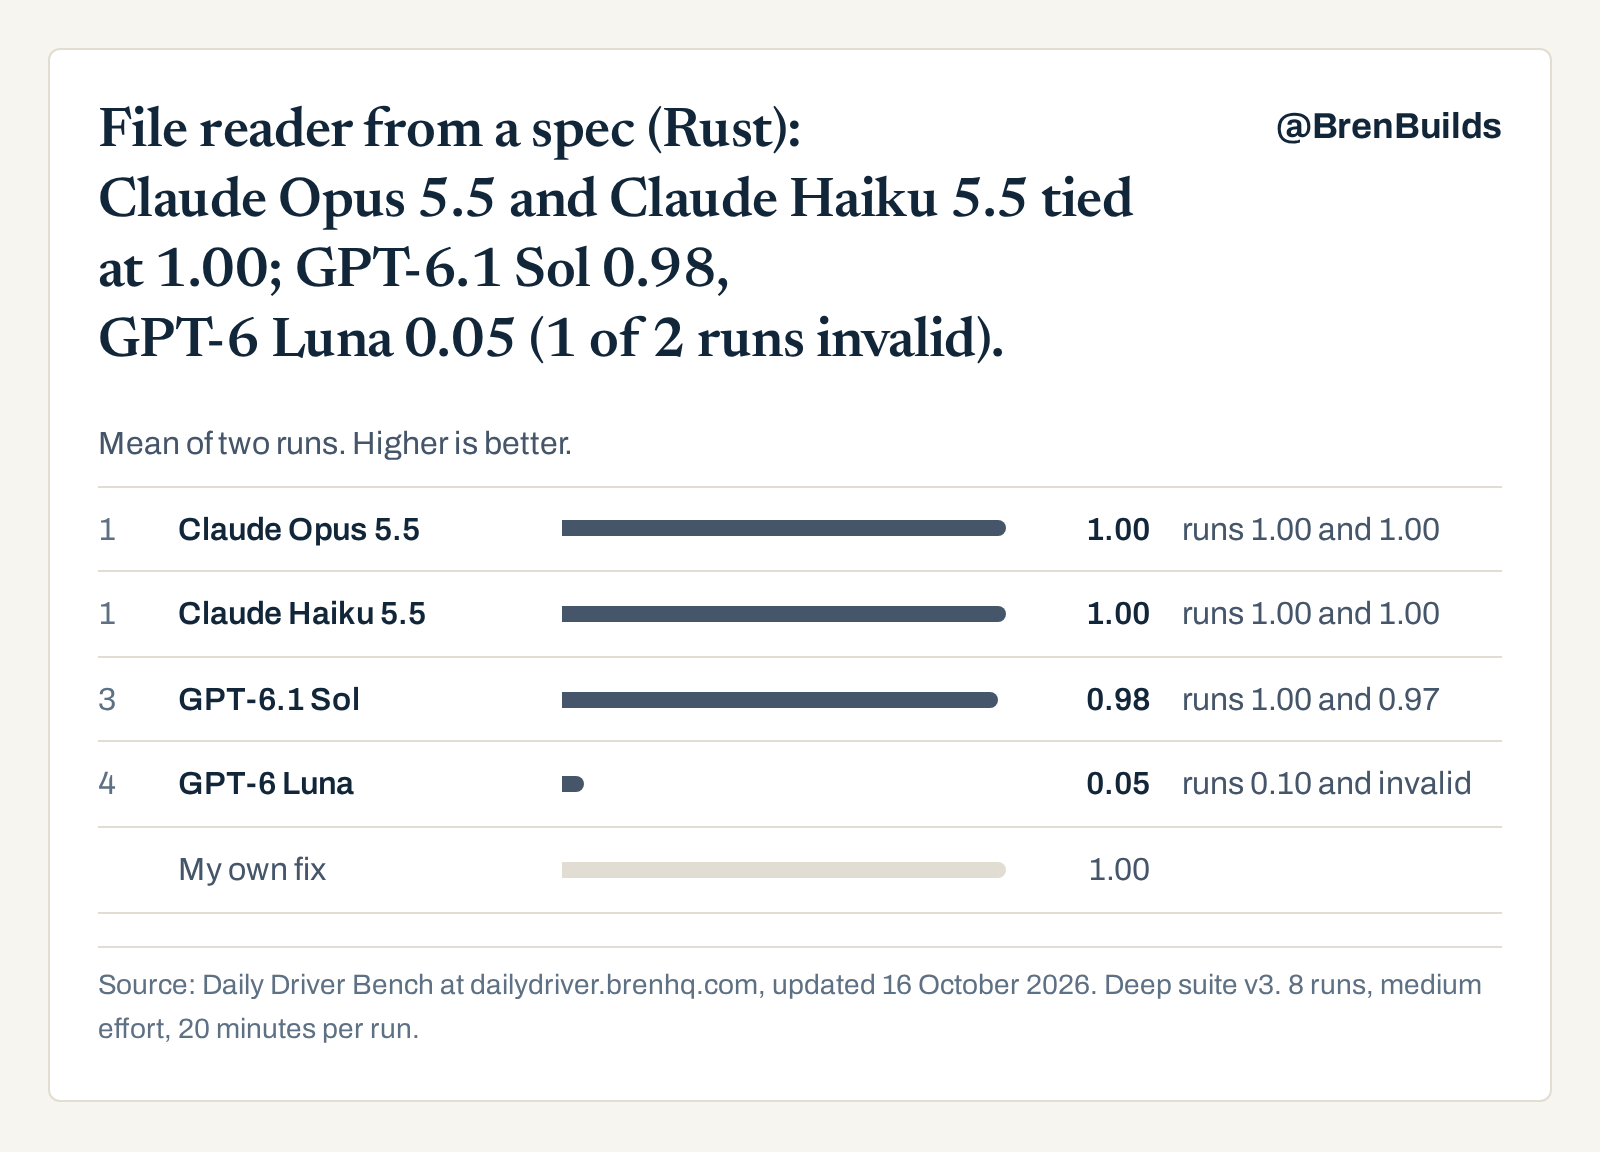
File reader from a spec (Rust): Claude Opus 5.5 and Claude Haiku 5.5 tied at 1.00; GPT-6.1 Sol 0.98, GPT-6 Luna 0.05 (1 of 2 runs invalid).
Write a reader for a data-file format from its public spec. The share of hidden files a run read exactly, 0 to 1. My own fix scored 1.00, the gray row. An invalid run's code didn't build or broke the project's own tests; it counts as 0 in the mean.
Mean of two runs. Higher is better.
- 1Claude Opus 5.51.00runs 1.00 and 1.00
- 1Claude Haiku 5.51.00runs 1.00 and 1.00
- 3GPT-6.1 Sol0.98runs 1.00 and 0.97
- 4GPT-6 Luna0.05runs 0.10 and invalid
- My own fix1.00
Each run, and the mean at 10 minutes
The code was saved at 10 minutes without stopping the model. A run that finished before then keeps its final score there.
| Score | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Run 1 | 1.00 | 1.00 | 1.00 | 0.10 |
| Run 2 | 0.97 | 1.00 | 1.00 | invalid |
| Mean | 0.98 | 1.00 | 1.00 | 0.05 |
| At 10 minutes, mean | 0.98 | 1.00 | 1.00 | 0.05 |
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 16 October 2026. Deep suite v3. 8 runs, medium effort, 20 minutes per run.
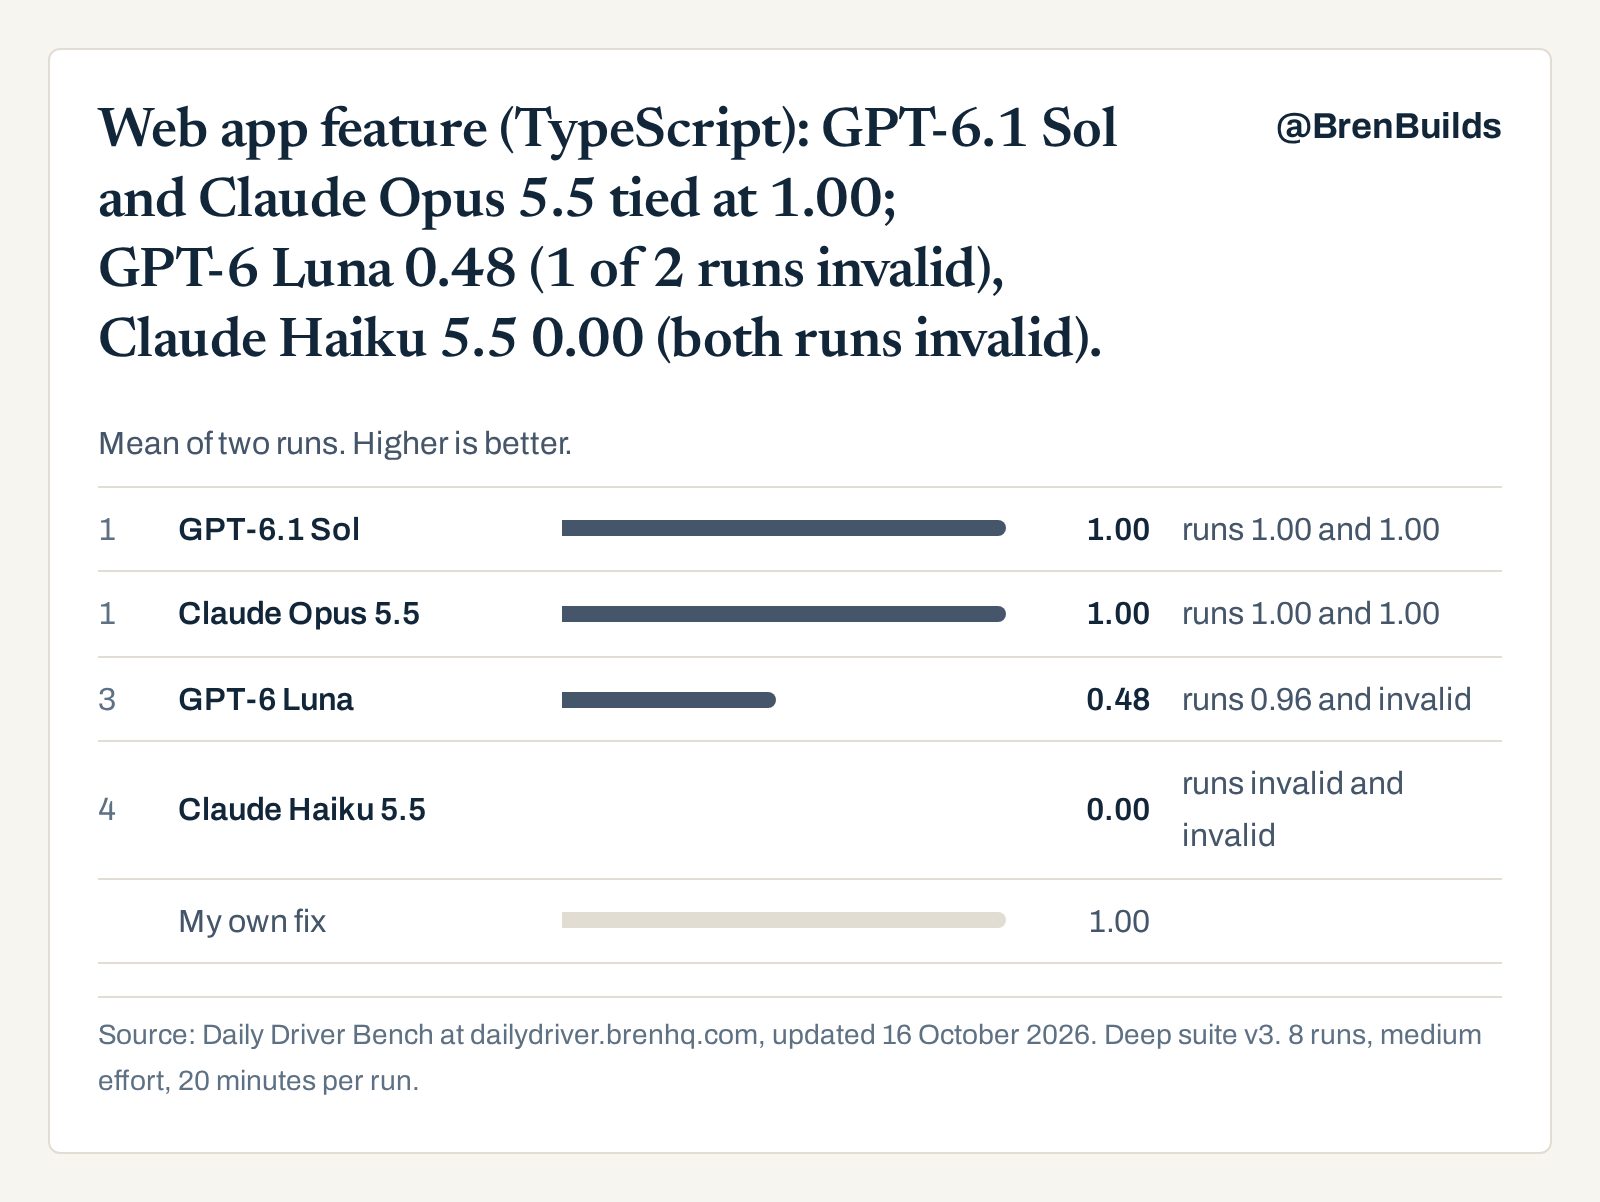
Web app feature (TypeScript): GPT-6.1 Sol and Claude Opus 5.5 tied at 1.00; GPT-6 Luna 0.48 (1 of 2 runs invalid), Claude Haiku 5.5 0.00 (both runs invalid).
Build a requested feature in a released open-source web app, end to end. The share of hidden checks a run passed, 0 to 1. My own fix scored 1.00, the gray row. An invalid run's code didn't build or broke the project's own tests; it counts as 0 in the mean.
Mean of two runs. Higher is better.
- 1GPT-6.1 Sol1.00runs 1.00 and 1.00
- 1Claude Opus 5.51.00runs 1.00 and 1.00
- 3GPT-6 Luna0.48runs 0.96 and invalid
- 4Claude Haiku 5.50.00runs invalid and invalid
- My own fix1.00
Each run, and the mean at 10 minutes
The code was saved at 10 minutes without stopping the model. A run that finished before then keeps its final score there.
| Score | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Run 1 | 1.00 | 1.00 | invalid | 0.96 |
| Run 2 | 1.00 | 1.00 | invalid | invalid |
| Mean | 1.00 | 1.00 | 0.00 | 0.48 |
| At 10 minutes, mean | 1.00 | 0.70 | 0.00 | 0.33 |
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 16 October 2026. Deep suite v3. 8 runs, medium effort, 20 minutes per run.
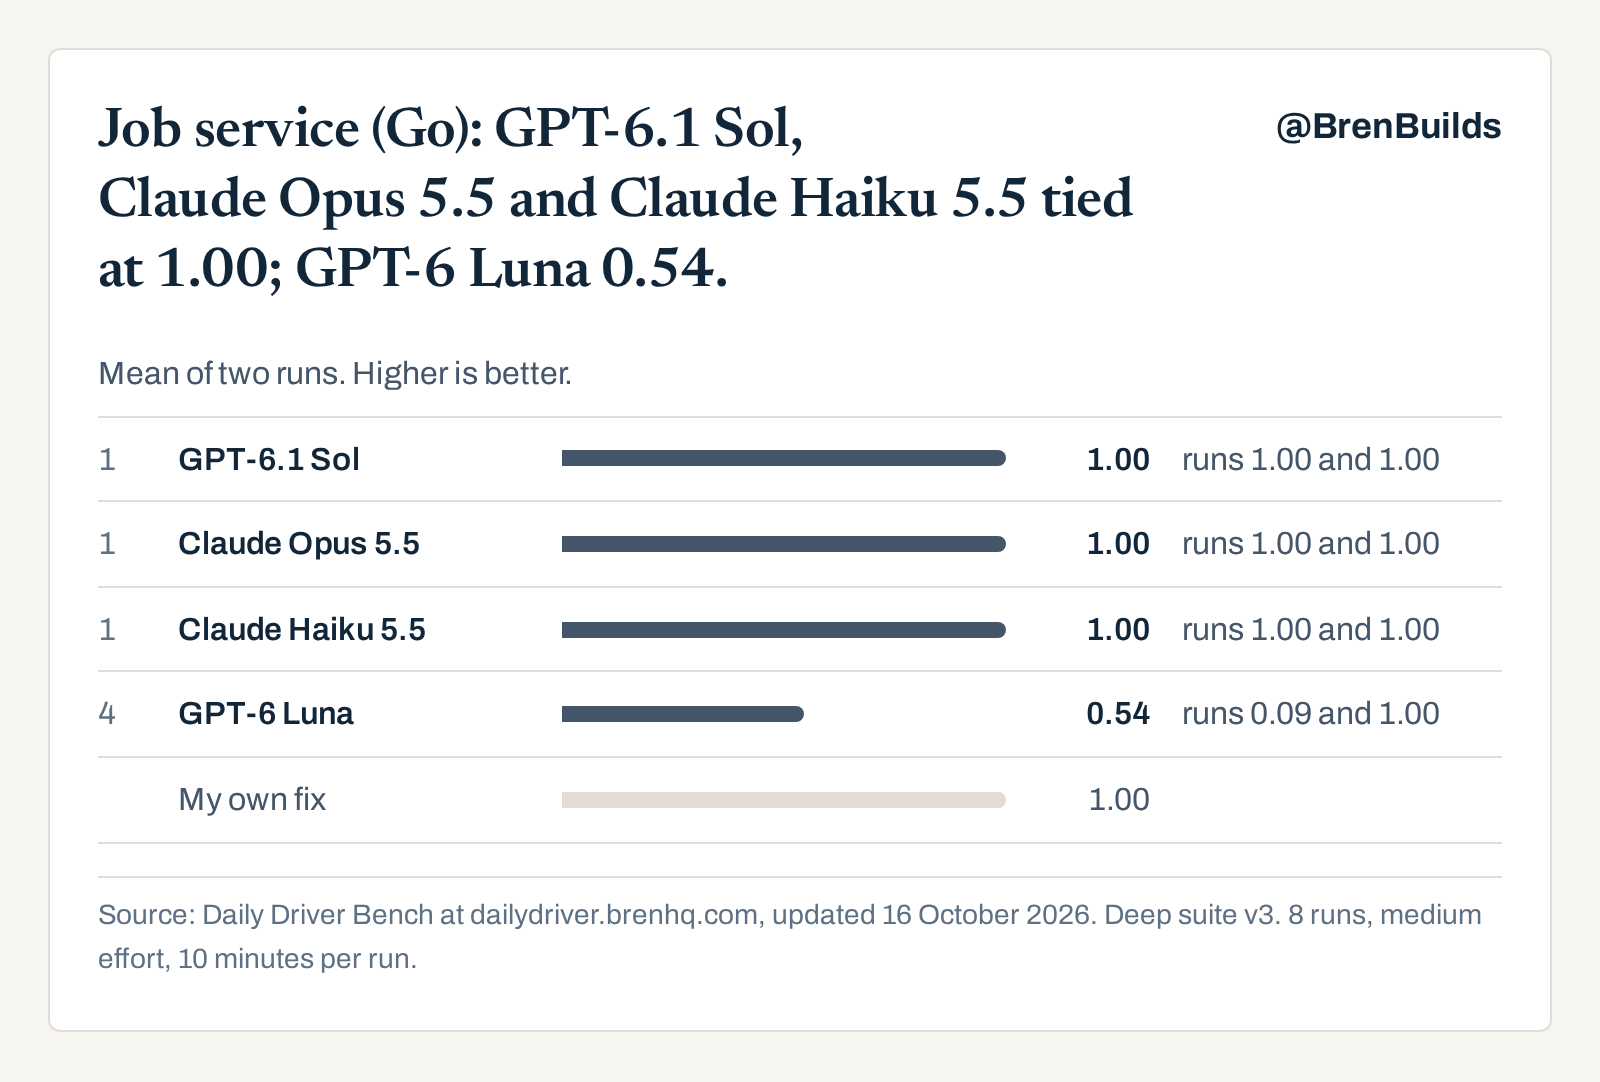
Job service (Go): GPT-6.1 Sol, Claude Opus 5.5 and Claude Haiku 5.5 tied at 1.00; GPT-6 Luna 0.54.
Ship two planned releases of my own job service, the second built on the first. The share of hidden checks a run passed, 0 to 1. My own fix scored 1.00, the gray row.
Mean of two runs. Higher is better.
- 1GPT-6.1 Sol1.00runs 1.00 and 1.00
- 1Claude Opus 5.51.00runs 1.00 and 1.00
- 1Claude Haiku 5.51.00runs 1.00 and 1.00
- 4GPT-6 Luna0.54runs 0.09 and 1.00
- My own fix1.00
Each run, and the mean at 5 minutes
The code was saved at 5 minutes without stopping the model. A run that finished before then keeps its final score there.
| Score | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Run 1 | 1.00 | 1.00 | 1.00 | 0.09 |
| Run 2 | 1.00 | 1.00 | 1.00 | 1.00 |
| Mean | 1.00 | 1.00 | 1.00 | 0.54 |
| At 5 minutes, mean | 1.00 | 0.40 | 0.49 | 0.54 |
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 16 October 2026. Deep suite v3. 8 runs, medium effort, 10 minutes per run.
Time#
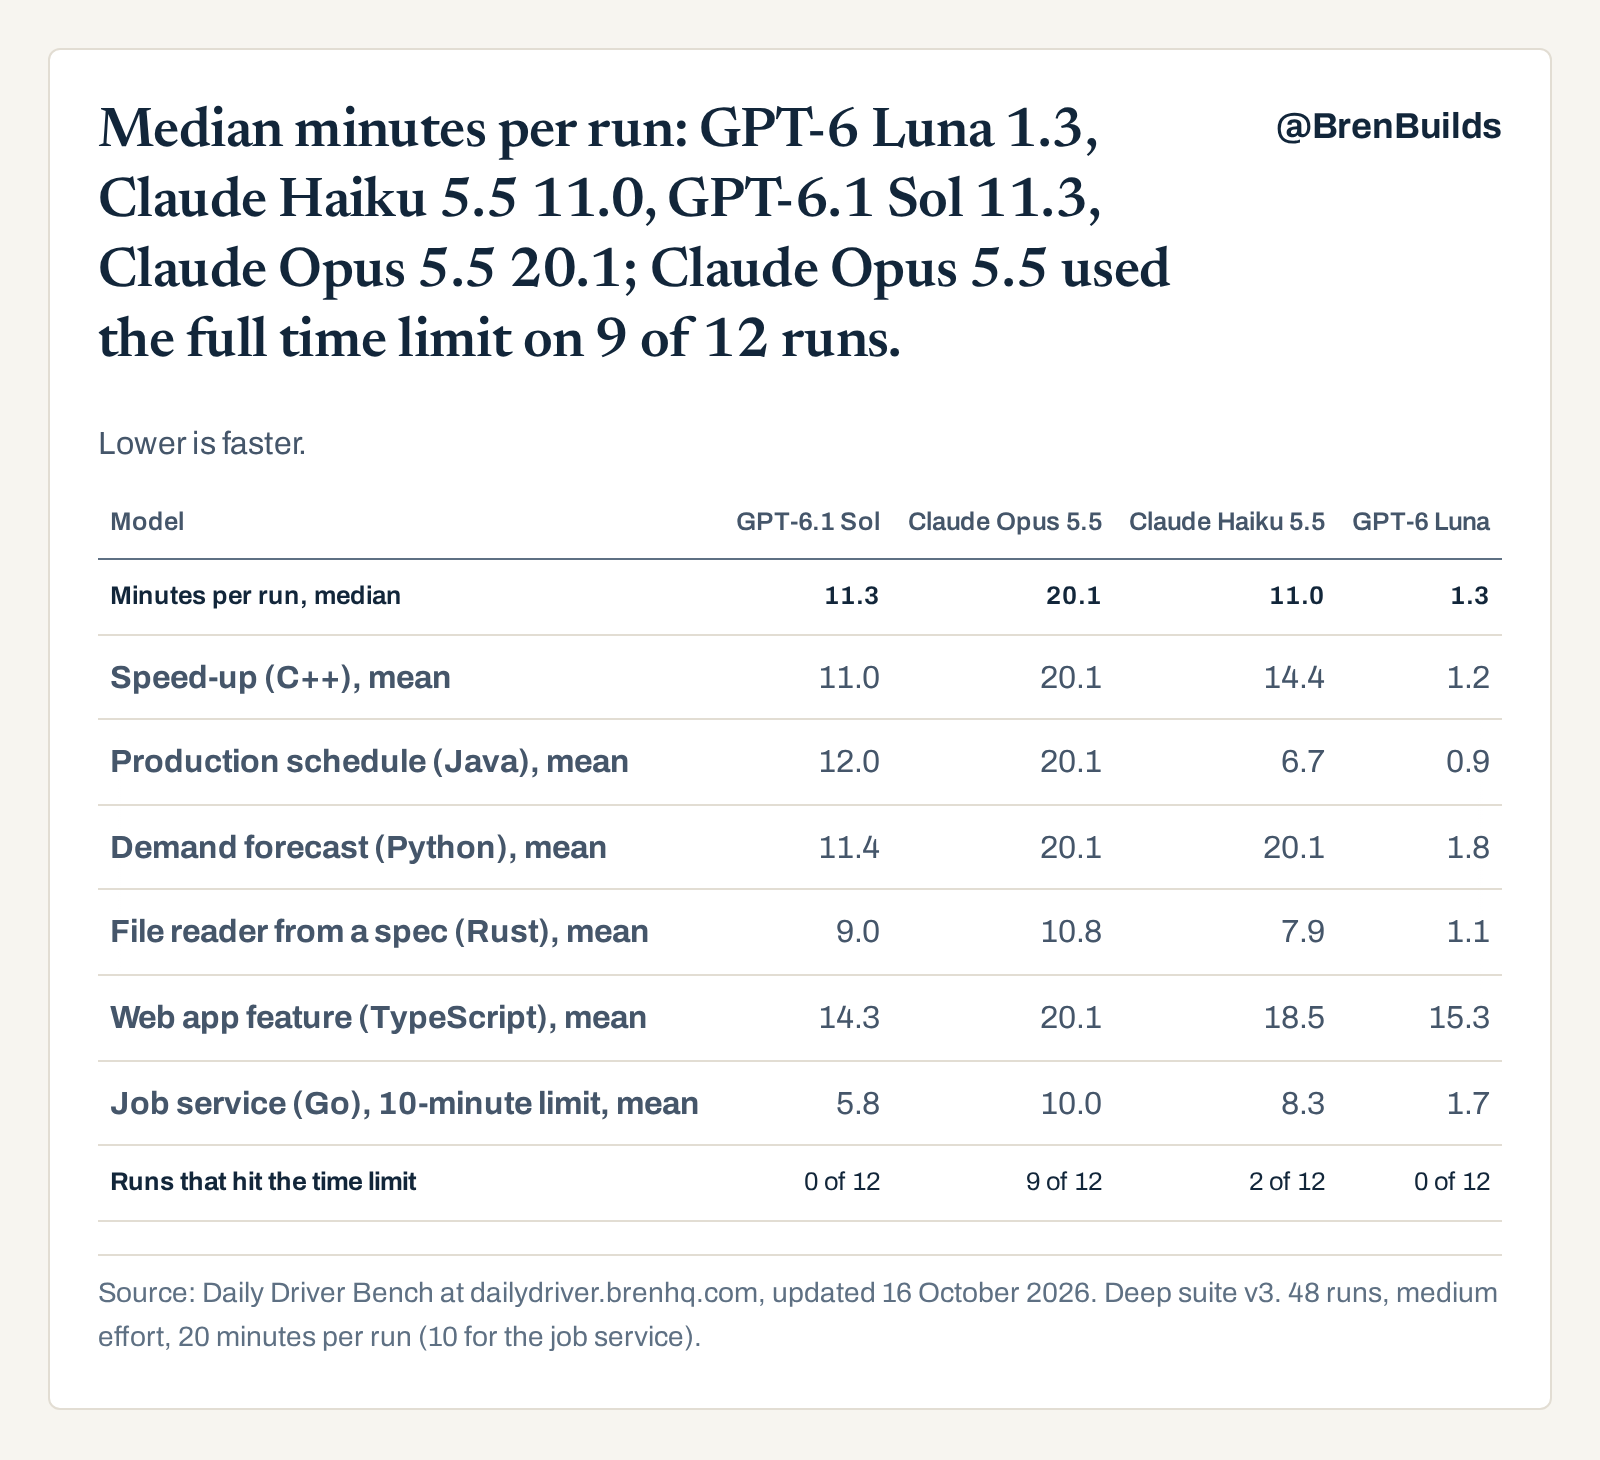
Median minutes per run: GPT-6 Luna 1.3, Claude Haiku 5.5 11.0, GPT-6.1 Sol 11.3, Claude Opus 5.5 20.1; Claude Opus 5.5 used the full time limit on 9 of 12 runs.
Minutes from start to finish, including stopping the tools, so a run stopped at the limit can read a little over it. A short run can mean a model stopped early, so read time beside the scores.
Lower is faster.
| Model | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Minutes per run, median | 11.3 | 20.1 | 11.0 | 1.3 |
| Speed-up (C++), mean | 11.0 | 20.1 | 14.4 | 1.2 |
| Production schedule (Java), mean | 12.0 | 20.1 | 6.7 | 0.9 |
| Demand forecast (Python), mean | 11.4 | 20.1 | 20.1 | 1.8 |
| File reader from a spec (Rust), mean | 9.0 | 10.8 | 7.9 | 1.1 |
| Web app feature (TypeScript), mean | 14.3 | 20.1 | 18.5 | 15.3 |
| Job service (Go), 10-minute limit, mean | 5.8 | 10.0 | 8.3 | 1.7 |
| Runs that hit the time limit | 0 of 12 | 9 of 12 | 2 of 12 | 0 of 12 |
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 16 October 2026. Deep suite v3. 48 runs, medium effort, 20 minutes per run (10 for the job service).
Cost#
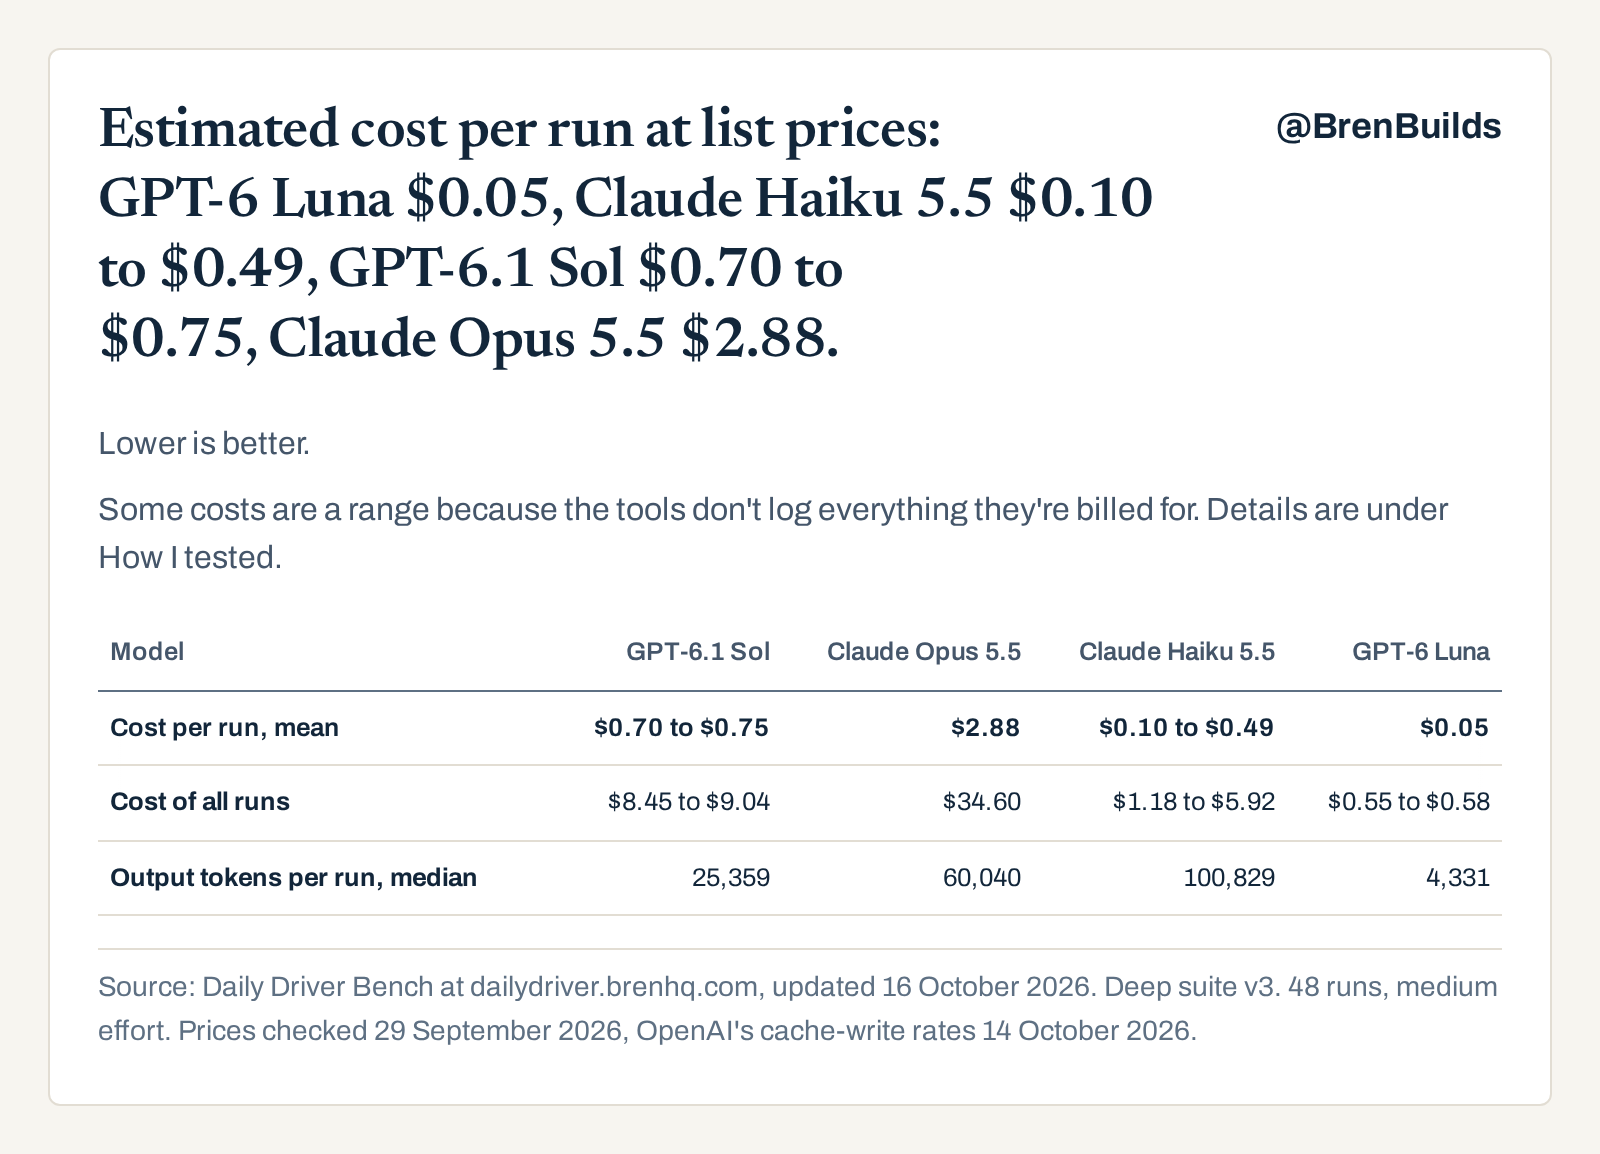
Estimated cost per run at list prices: GPT-6 Luna $0.05, Claude Haiku 5.5 $0.10 to $0.49, GPT-6.1 Sol $0.70 to $0.75, Claude Opus 5.5 $2.88.
An estimate at each vendor's list prices from the tokens each run used, invalid runs included. 11 Claude runs hit the time limit before Claude Code logged usage, so their tokens were counted from each run's own requests. I paid through subscriptions, not these amounts.
Lower is better.
Some costs are a range because the tools don't log everything they're billed for. Details are under How I tested.
| Model | GPT-6.1 Sol | Claude Opus 5.5 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|---|
| Cost per run, mean | $0.70 to $0.75 | $2.88 | $0.10 to $0.49 | $0.05 |
| Cost of all runs | $8.45 to $9.04 | $34.60 | $1.18 to $5.92 | $0.55 to $0.58 |
| Output tokens per run, median | 25,359 | 60,040 | 100,829 | 4,331 |
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 16 October 2026. Deep suite v3. 48 runs, medium effort. Prices checked 29 September 2026, OpenAI's cache-write rates 14 October 2026.
How I tested#
How the tasks were made, run and graded
In version 2 the two strongest models passed every run, so its scores couldn't tell them apart. For version 3 I wrote six tasks in six languages: two in real open-source code as released, four in applications I wrote for the suite. Three are open-ended: they measure how much a run improved the code, on a log2 scale, and aren't capped at my own fix's score; the other three score the share of hidden checks a run gets right. Each task keeps its own score, so there is no overall number or rank. Tasks, prompts and graders are private so later runs stay fair.
The hidden checks and hidden data never enter the model's container, and every model got the same seeds. A run whose code doesn't build or breaks the project's own tests is invalid and scores 0. Fable 5.1 and GPT-6 Astra reviewed the plan before the counted runs began; trial runs aren't counted.
This is version 3, frozen 15 October 2026: 6 tasks, 2 runs each, the same settings and the same containers for every model. Each version tests something different, so scores don't carry over from earlier versions.
Claude Opus 5.5 and Claude Haiku 5.5 ran in Claude Code 2.1.284, and GPT-6.1 Sol and GPT-6 Luna in Codex CLI 0.159.0, all at medium effort, 20 minutes per run (10 for the job service). The code was saved at the halfway point without stopping the model, and that copy was graded too. 11 runs hit the limit and were graded on the code at that point. Each run ran in its own container with no internet except the model's API, and was graded in a fresh container. Tasks that measure time were graded one run at a time with nothing else running. Runs were paced to stay under a fixed share of each subscription's usage.
Costs are estimates at each vendor's standard list prices, from the tokens each run used. Claude Code logs no usage for a run stopped at the time limit, so for those 11 Claude runs I counted the tokens from the run's own requests, the same way Claude Code counts them on runs that finished. Claude Haiku 5.5 is a range because Anthropic charges more for prompts over 100k tokens and prompt sizes weren't logged; GPT costs are a range because Codex doesn't log cache writes, which OpenAI bills at 1.25 times the input price. The runs ran on subscriptions, so these are not what was spent.
Limits: 6 tasks and 2 runs each, one tool and one effort setting per model. Two runs can't show which gaps would hold up over more runs, so none is called significant here.
Every run's task, score, time and cost is in results.json, under deep_v3_runs and deep_v3_suite.