GPT-6.1 Sol, timed day by day
OpenAI's @thsottiaux posted on 5 October: "Reaching 50 TPS instead of 30TPS". I timed the same small Codex job before and after.
Every sitting#
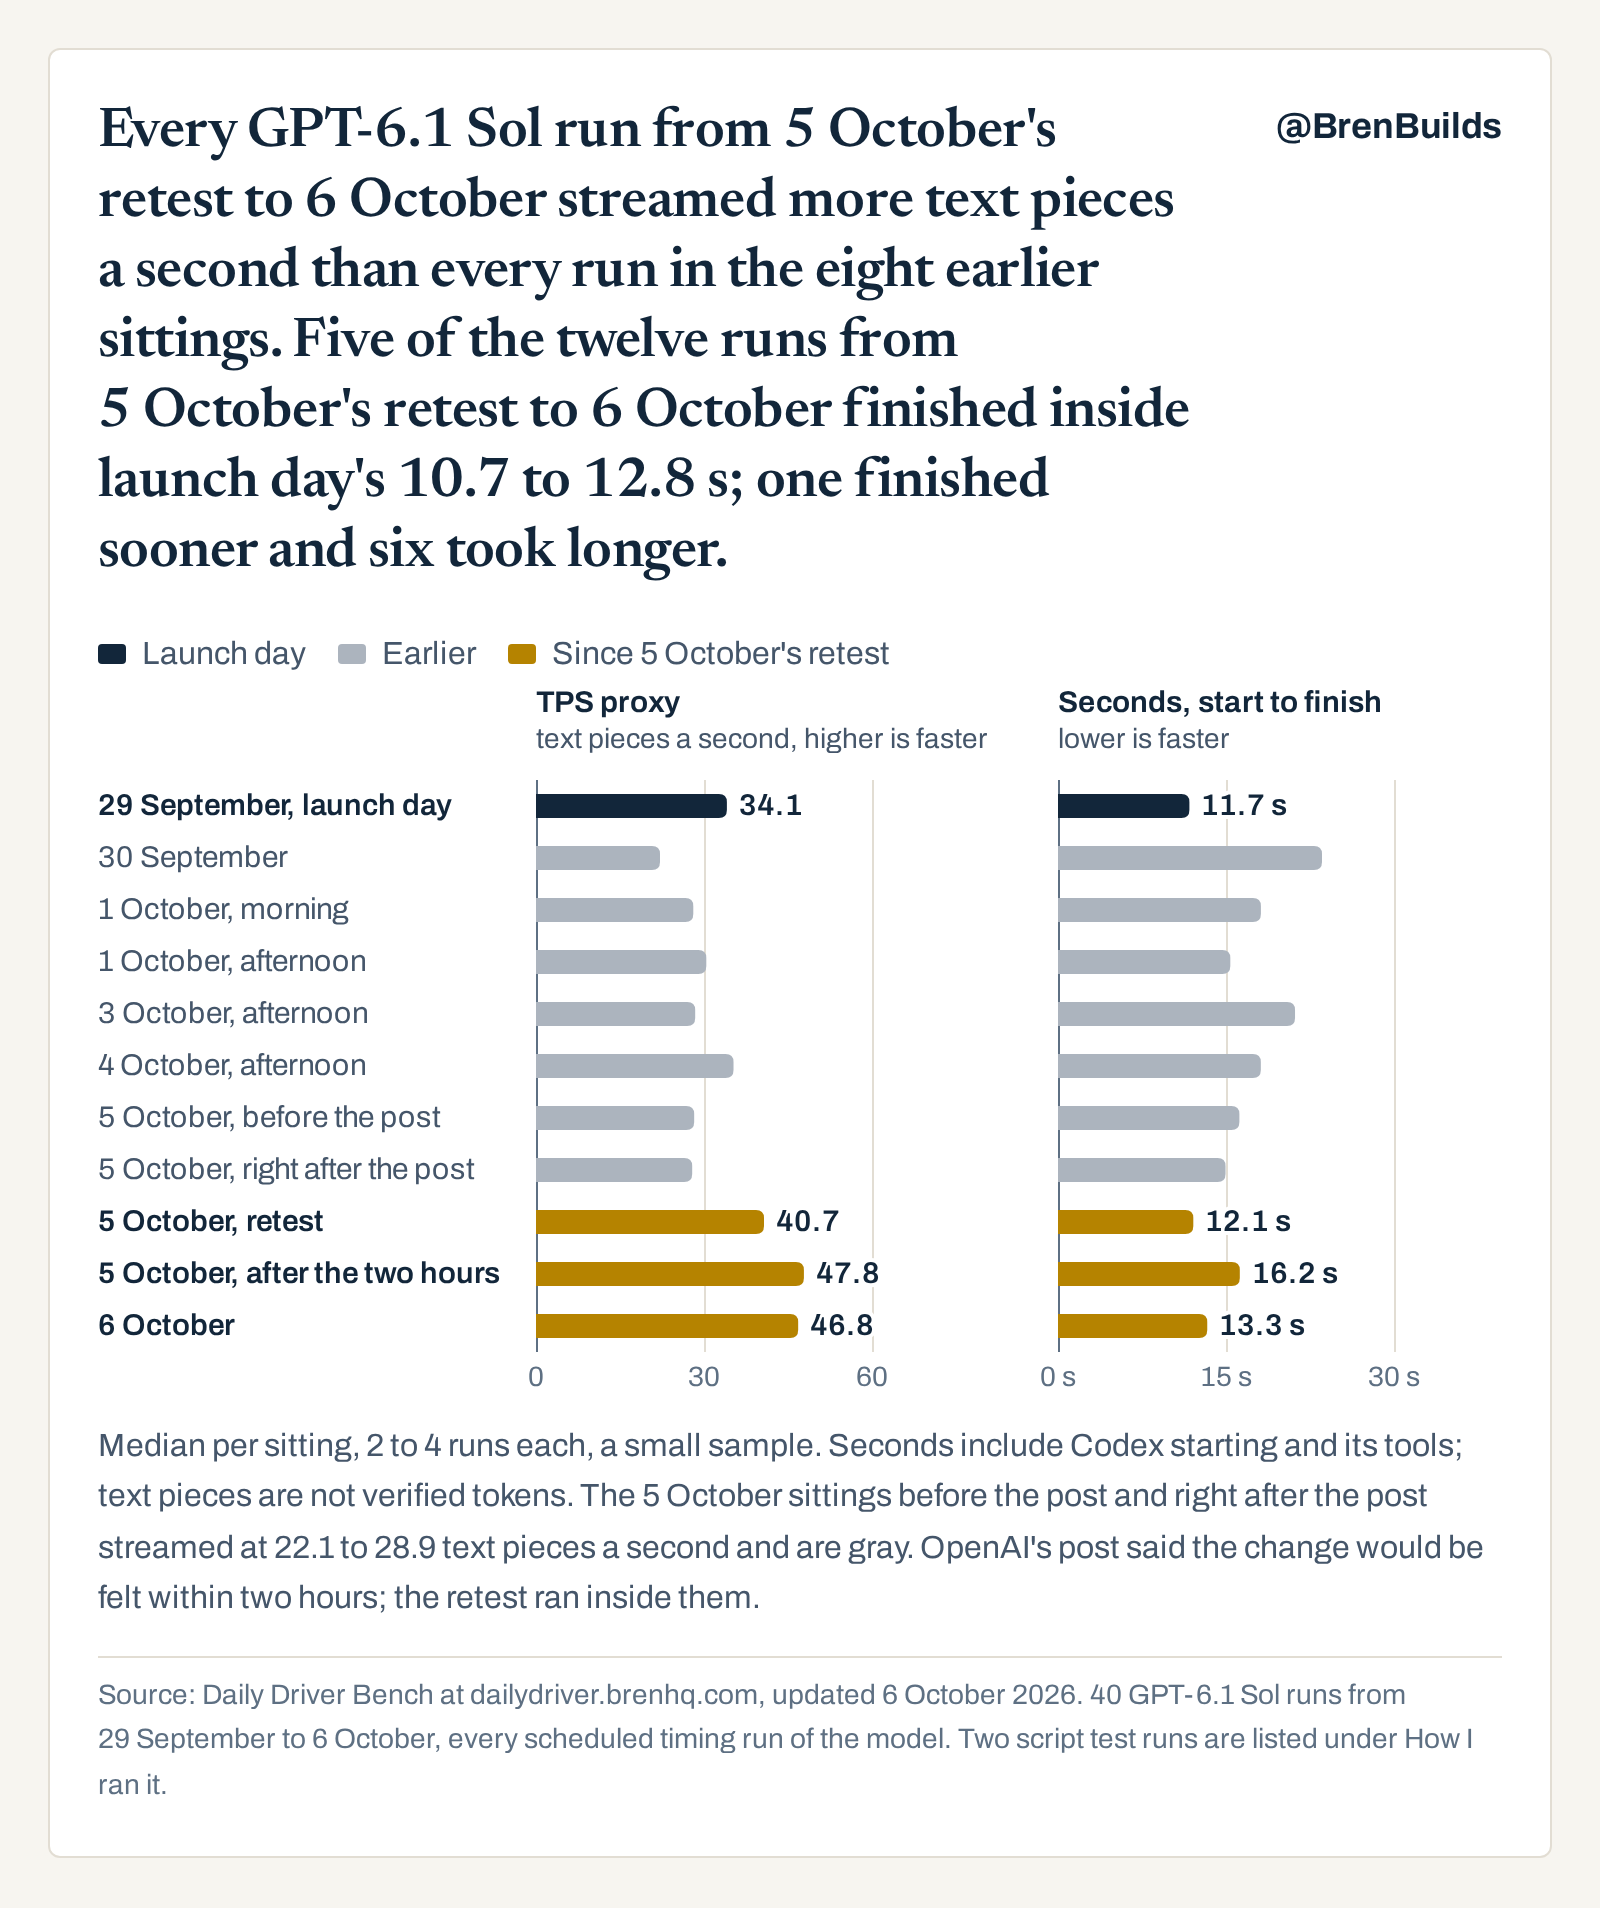
Every GPT-6.1 Sol run from 5 October's retest to 6 October streamed more text pieces a second than every run in the eight earlier sittings. Five of the twelve runs from 5 October's retest to 6 October finished inside launch day's 10.7 to 12.8 s; one finished sooner and six took longer.
Hover or tap a row for its range; every run is in the table.
- Launch day
- Earlier
- Since 5 October's retest
Median per sitting, 2 to 4 runs each, a small sample. Seconds include Codex starting and its tools; text pieces are not verified tokens. The 5 October sittings before the post and right after the post streamed at 22.1 to 28.9 text pieces a second and are gray. OpenAI's post said the change would be felt within two hours; the retest ran inside them.
The table scrolls sideways on a small screen.
| 29 September, launch day | 1 | 12.8 s | 220 | 34.0 | |
|---|---|---|---|---|---|
| 29 September, launch day | 2 | 10.7 s | 211 | 34.1 | |
| 30 September | 1 | 24.9 s | 250 | 22.3 | |
| 30 September | 2 | 22.2 s | 290 | 22.0 | |
| 1 October, morning | 1 | 19.6 s | 302 | 29.7 | |
| 1 October, morning | 2 | 16.6 s | 204 | 20.9 | |
| 1 October, morning | 3 | 16.6 s | 253 | 29.9 | |
| 1 October, morning | 4 | 19.7 s | 282 | 26.5 | |
| 1 October, afternoon | 1 | 15.0 s | 216 | 29.9 | |
| 1 October, afternoon | 2 | 13.5 s | 208 | 28.1 | |
| 1 October, afternoon | 3 | 16.8 s | 274 | 34.0 | |
| 1 October, afternoon | 4 | 15.8 s | 257 | 30.9 | |
| 3 October, afternoon | 1 | 21.8 s | 312 | 32.3 | |
| 3 October, afternoon | 2 | 20.6 s | 290 | 29.2 | |
| 3 October, afternoon | 3 | 15.6 s | 212 | 27.0 | |
| 3 October, afternoon | 4 | 26.6 s | 306 | 27.6 | |
| 4 October, afternoon | 1 | 22.9 s | 297 | 34.4 | |
| 4 October, afternoon | 2 | 20.1 s | 258 | 35.5 | |
| 4 October, afternoon | 3 | 16.1 s | 247 | 35.1 | |
| 4 October, afternoon | 4 | 13.2 s | 213 | 35.7 | |
| 5 October, before the post | 1 | 17.0 s | 267 | 28.9 | |
| 5 October, before the post | 2 | 18.6 s | 222 | 22.1 | |
| 5 October, before the post | 3 | 14.1 s | 213 | 28.4 | |
| 5 October, before the post | 4 | 15.4 s | 241 | 28.1 | |
| 5 October, right after the post | 1 | 15.1 s | 243 | 28.4 | |
| 5 October, right after the post | 2 | 14.8 s | 211 | 27.9 | |
| 5 October, right after the post | 3 | 19.5 s | 302 | 27.3 | |
| 5 October, right after the post | 4 | 14.3 s | 224 | 27.9 | |
| 5 October, retest | 1 | 12.4 s | 263 | 43.2 | 44.1 |
| 5 October, retest | 2 | 11.8 s | 232 | 37.7 | 38.6 |
| 5 October, retest | 3 | 20.8 s | 305 | 38.2 | 39.0 |
| 5 October, retest | 4 | 11.3 s | 253 | 48.4 | 49.5 |
| 5 October, after the two hours | 1 | 15.3 s | 306 | 50.9 | 51.9 |
| 5 October, after the two hours | 2 | 17.7 s | 299 | 39.2 | 40.0 |
| 5 October, after the two hours | 3 | 17.2 s | 284 | 52.9 | 54.1 |
| 5 October, after the two hours | 4 | 11.4 s | 254 | 44.8 | 45.7 |
| 6 October | 1 | 15.7 s | 281 | 42.4 | 43.4 |
| 6 October | 2 | 10.3 s | 243 | 48.4 | 49.4 |
| 6 October | 3 | 15.1 s | 271 | 45.3 | 46.3 |
| 6 October | 4 | 11.6 s | 245 | 50.1 | 51.2 |
All output tokens: every request in the run. Text pieces/s: answer text events received a second, first to last, pauses included; a piece is not a verified token. TPS: OpenAI's own output-token count for the answer over the same seconds, a rate observed at my machine that may include a few non-text tokens; logged for the twelve runs since 5 October's retest, so earlier rows stay blank.
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 6 October 2026. 40 GPT-6.1 Sol runs from 29 September to 6 October, every scheduled timing run of the model. Two script test runs are listed under How I ran it.
The race#
- 29 Sep, launch day: 10.7 s and 12.8 s
- 30 Sep: 22.2 s and 24.9 s
- 1 Oct, morning: 16.6 to 19.7 s
- 1 Oct, afternoon: 13.5 to 16.8 s
- 3 Oct, afternoon: 15.6 to 26.6 s
- 4 Oct, afternoon: 13.2 to 22.9 s
- 5 Oct, before the post: 14.1 to 18.6 s
- 5 Oct, right after the post: 14.3 to 19.5 s
- 5 Oct, retest: 11.3 to 20.8 s
- 5 Oct, after the two hours: 11.4 to 17.7 s
- 6 Oct: 10.3 to 15.7 s
Same day, other models#
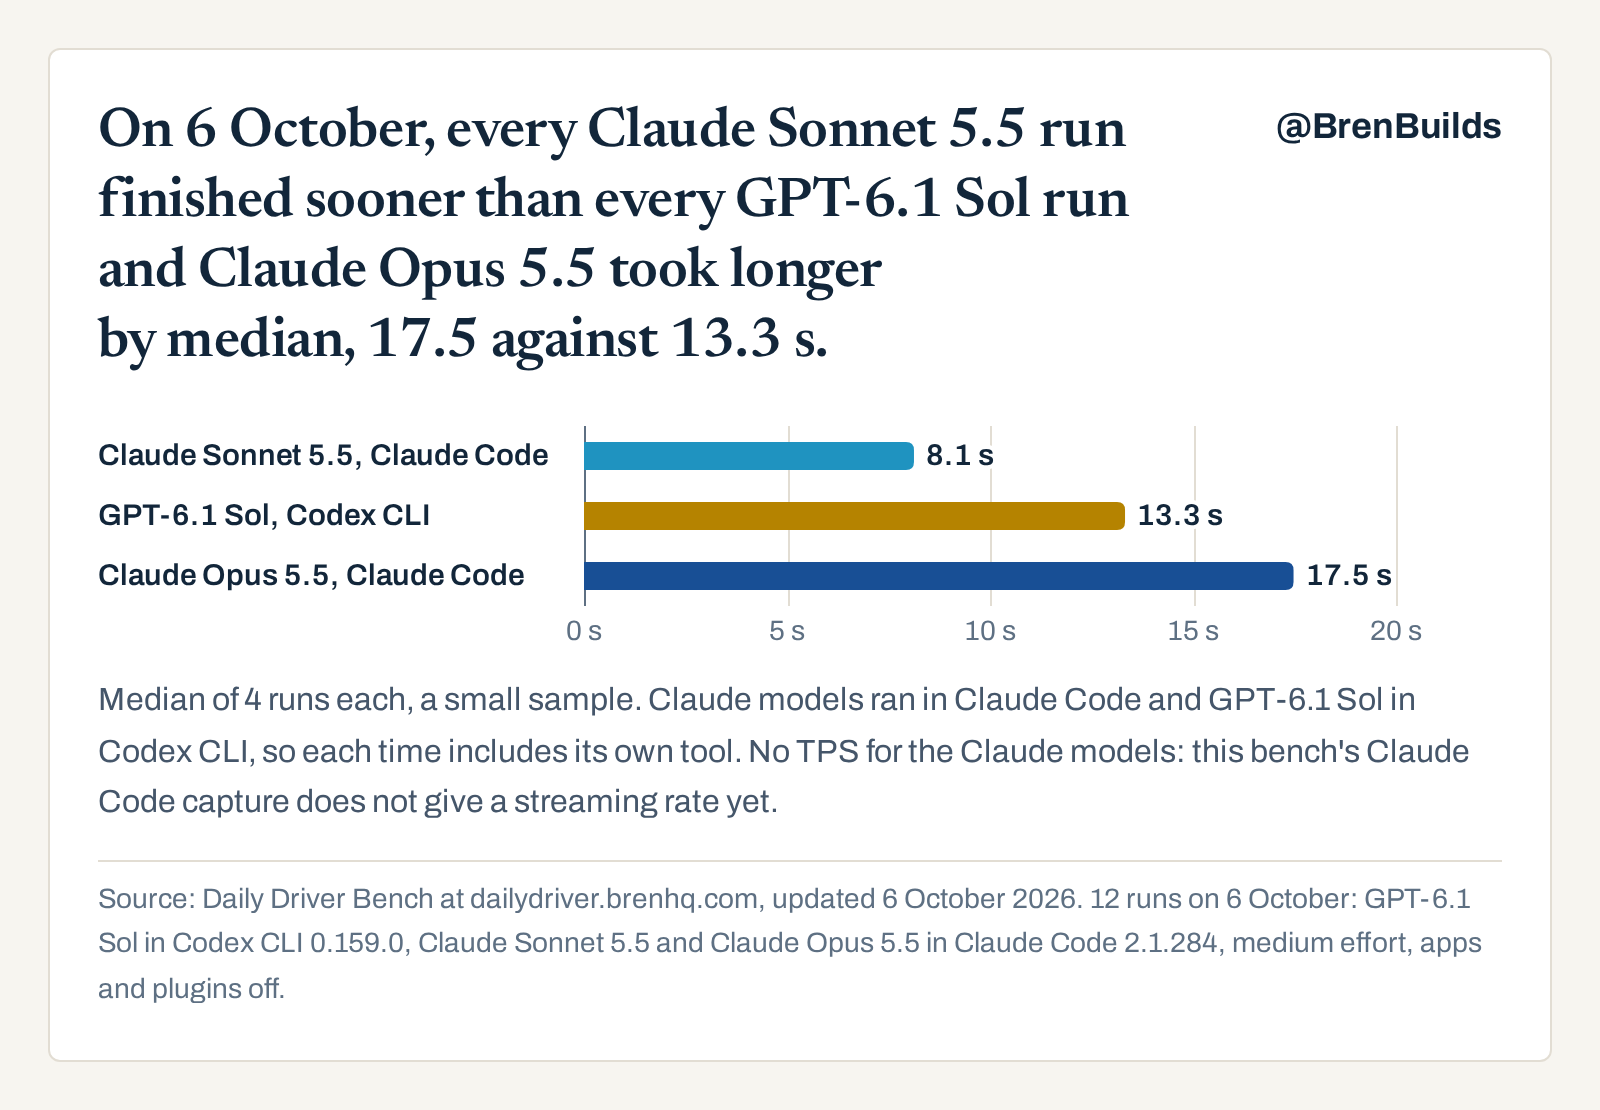
On 6 October, every Claude Sonnet 5.5 run finished sooner than every GPT-6.1 Sol run and Claude Opus 5.5 took longer by median, 17.5 against 13.3 s.
Median seconds start to finish, same task and day, 4 runs each. Hover or tap a row for every run.
Median of 4 runs each, a small sample. Claude models ran in Claude Code and GPT-6.1 Sol in Codex CLI, so each time includes its own tool. No TPS for the Claude models: this bench's Claude Code capture does not give a streaming rate yet.
All ten models, timed on 30 September, are on the Quick suite page.
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 6 October 2026. 12 runs on 6 October: GPT-6.1 Sol in Codex CLI 0.159.0, Claude Sonnet 5.5 and Claude Opus 5.5 in Claude Code 2.1.284, medium effort, apps and plugins off.
How I ran it#
Background, method and definitions
OpenAI's @thsottiaux posted on 30 September that added capacity would bring "almost twice the speed compared to what we served yesterday". On 1 October @sama posted: "Should be much better now!" On 2 and 4 October posts on X still called it slow. I timed it again on 3, 4, 5 and 6 October. On 5 October @thsottiaux posted that the change "should be felt within the next two hours"; I timed it before that post, right after it, in a retest inside the two hours and after them. The group since 5 October's retest starts at that retest, the first sitting inside the two hours. I set it after seeing the 5 October runs, and every later sitting joins it, whatever it shows.
Each run starts Codex CLI 0.159.0, OpenAI's command-line coding tool, on a fresh copy of a small Python project in the bench's Docker container. GPT-6.1 Sol, at medium effort, reads the project's 53-line file and explains in plain English how it adds up monthly totals and what happens with a bad date, without changing anything. The clock runs from starting Codex until it exits, and the runs go one at a time. A run passes when its answer contains both "month" and "ValueError". All 40 runs passed. Two test runs of the updated timing script on 5 October, between the sitting right after the post and the retest, are not charted. They took 18.4 s and 11.7 s, streamed at 35.4 and 42.4 text pieces a second, 36.2 and 43.4 by OpenAI's token count, and both passed.
On launch day Codex also loaded the apps and plugins that come with a ChatGPT login, and I have switched them off since. On 1 October I ran four runs with them on and four with them off: 15.8 to 19.7 s and 13.5 to 19.6 s, all slower than launch day, so turning them on did not bring back launch day's times.
Both rates are timed from the stream: each answer text event OpenAI sends is timestamped as Codex receives it, and a rate is a count over the seconds from the first text event to the last, pauses included. Text pieces/s counts those events; a piece is not a verified token, so it is labeled a proxy. TPS counts OpenAI's own output tokens for the answer reply, logged for the twelve runs since 5 October's retest and two script tests before it. That count may include a few non-text tokens (it was 4 above the pieces on every run with both) and includes the first output, so it is a rate observed at my machine for the answer, not the engine's generation speed. Each run is one short answer on a ChatGPT subscription, so neither compares with API benchmarks. OpenAI's server-side time between tokens is a separate engine measure and is not shown. The CSV also has tokens a second of waiting: all output tokens divided by the seconds from each reply opening until it completes, added up.
The answer's stream is under half of every run. Launch day's answers were shorter, 157 and 152 pieces of text against 166 to 203 since 5 October's retest, so at 34.0 and 34.1 a second they streamed in 4.6 s and 4.5 s, inside the 3.3 to 5.1 s since. Every launch run made two model requests. The six runs since that made two finished in 10.3 to 12.4 s, against launch day's 10.7 to 12.8 s; the six that made more took 15.1 to 20.8 s.
The Quick suite page times every model on this task and keeps the 30 September runs. The run records are in results.json, under timing_runs and speed_recheck_runs, model gpt-6.1-sol.