Coding models and token-saving skills, measured
I run a quick suite and a deep suite of coding tasks myself in Claude Code, Codex CLI or Cursor CLI. Every number comes from one public file.
- Runs published
- 1,477
- Models
- 13
- Latest run
- 16 October 2026
Deep suite: score against estimated cost
Speed-up (C++), one of six tasks, four models. Higher is better, and left is cheaper.
- Claude models in Claude Code
- GPT models in Codex CLI
Show as a table
| Model | Score | Cost per run | Output tokens | Minutes | Frontier |
|---|---|---|---|---|---|
| GPT-6 Luna | 0.07 | $0.014 to $0.016 | 2,948 | 1.2 | on it |
| Claude Haiku 5.5 | 1.01 | $0.14 to $0.72 | 107,036 | 14.4 | on it |
| GPT-6.1 Sol | 1.08 | $0.71 to $0.76 | 27,653 | 11.0 | on it |
| Claude Opus 5.5 | 1.66 | $4.00 | 89,104 | 20.1 | on it |
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 16 October 2026. Deep suite v3 has six tasks and 48 runs, all at medium effort. Each dot is a model's mean on the chart's scale, and an invalid run counts as 0. 11 of the 48 runs hit the time limit and were graded on the code at that point, nine of them Claude Opus 5.5's. A dot sits at the middle of its estimated cost range.
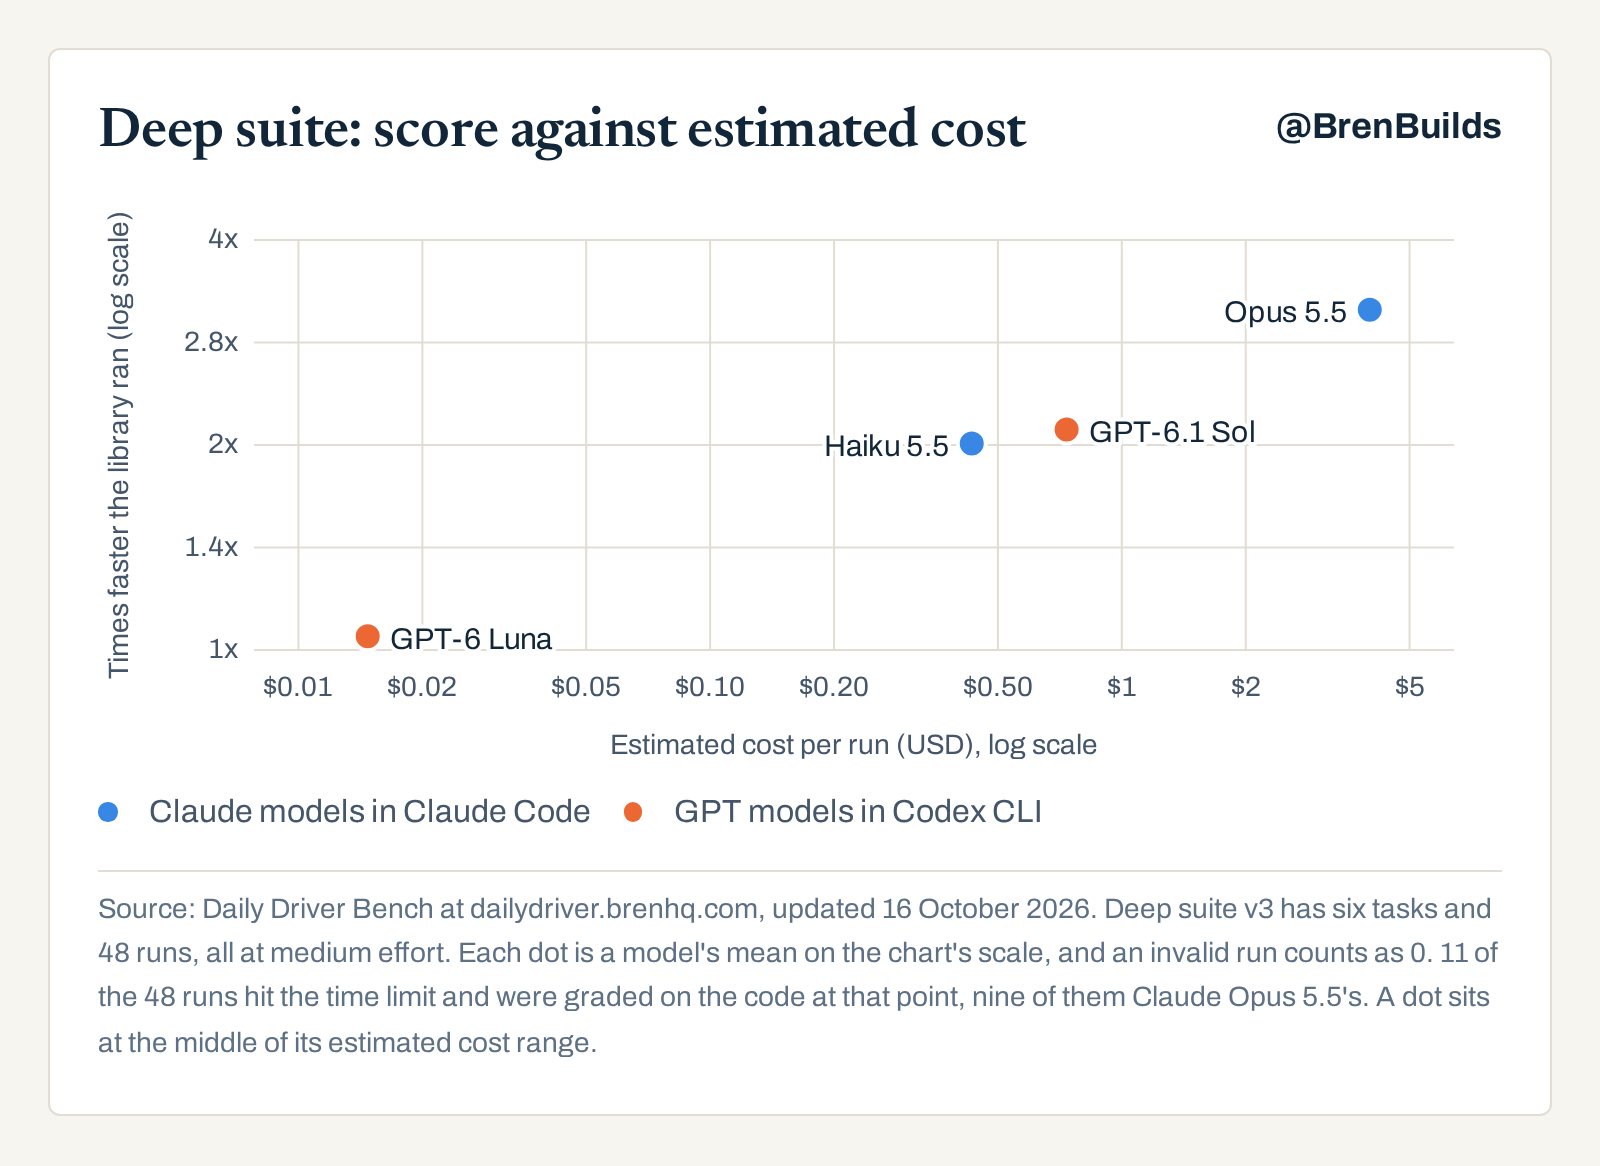
- Deep suiteClaude Opus 5.5 had the best average on five of six tasks, two alone and three tied. It also had the highest estimated cost on all six.Two runs per model on each task.
- SkillsToken-saving skills hit their claim in 1 of 29 checks.Numbered claims from two skills, checked on six models.
- Quick suiteOn the 30 September tickets test, GPT-6.1 Sol had the lowest estimated cost and Claude Sonnet 5.5 the fastest typical run.Five models, three runs each.
- New modelsMeta's Muse Wonder cost an estimated $0.748 a typical tickets-test run.Tested 16 October 2026, four days after its release.