Muse Wonder vs Claude Opus 5.5, GPT-6.1 Sol and Gemini 4 Argon
Meta released Muse Wonder on 12 October. On 16 October I ran it through my quick suite in Cursor CLI, beside Claude Opus 5.5, GPT-6.1 Sol and Gemini 4 Argon. This is Muse Wonder, not Muse Wonder Full, which Meta offers only in its Muse Code app.
Speed#
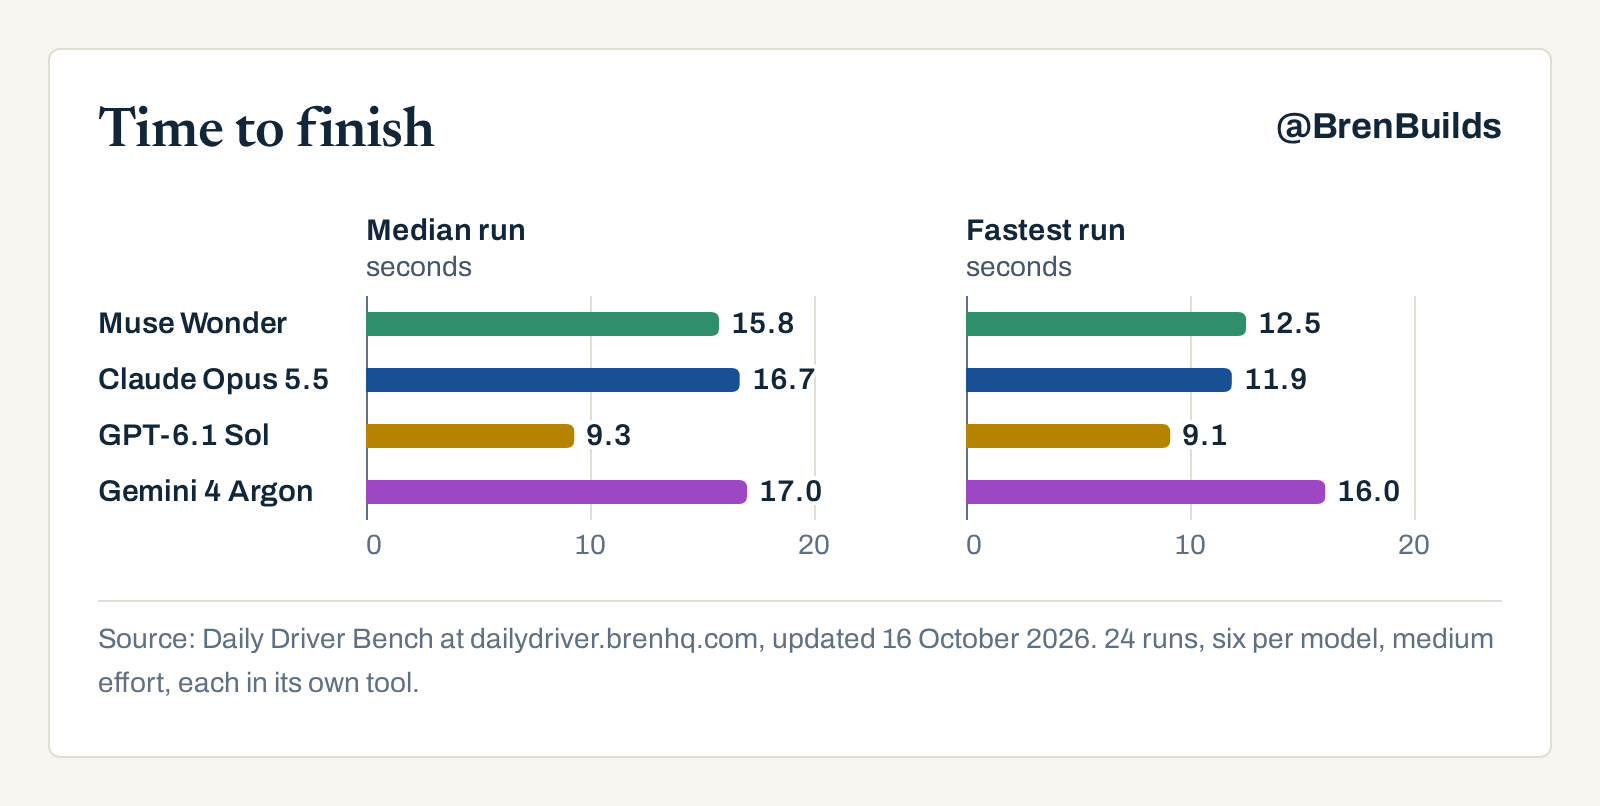
Time to finish
Seconds from starting the tool to its exit, one short explain task. Lower is better.
| Model | Tool | Run 1 | Run 2 | Run 3 | Run 4 | Run 5 | Run 6 |
|---|---|---|---|---|---|---|---|
| Muse Wonder | Cursor CLI | 27.0 s | 12.5 s | 13.7 s | 15.8 s | 15.7 s | 16.4 s |
| Claude Opus 5.5 | Claude Code | 16.4 s | 19.4 s | 18.5 s | 11.9 s | 16.9 s | 16.4 s |
| GPT-6.1 Sol | Codex CLI | 9.8 s | 9.1 s | 9.3 s | 9.3 s | 9.2 s | 11.7 s |
| Gemini 4 Argon | Cursor CLI | 17.4 s | 16.7 s | 129.2 s | 16.3 s | 16.0 s | 26.0 s |
The table scrolls sideways on a small screen.
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 16 October 2026. 24 runs, six per model, medium effort, each in its own tool.
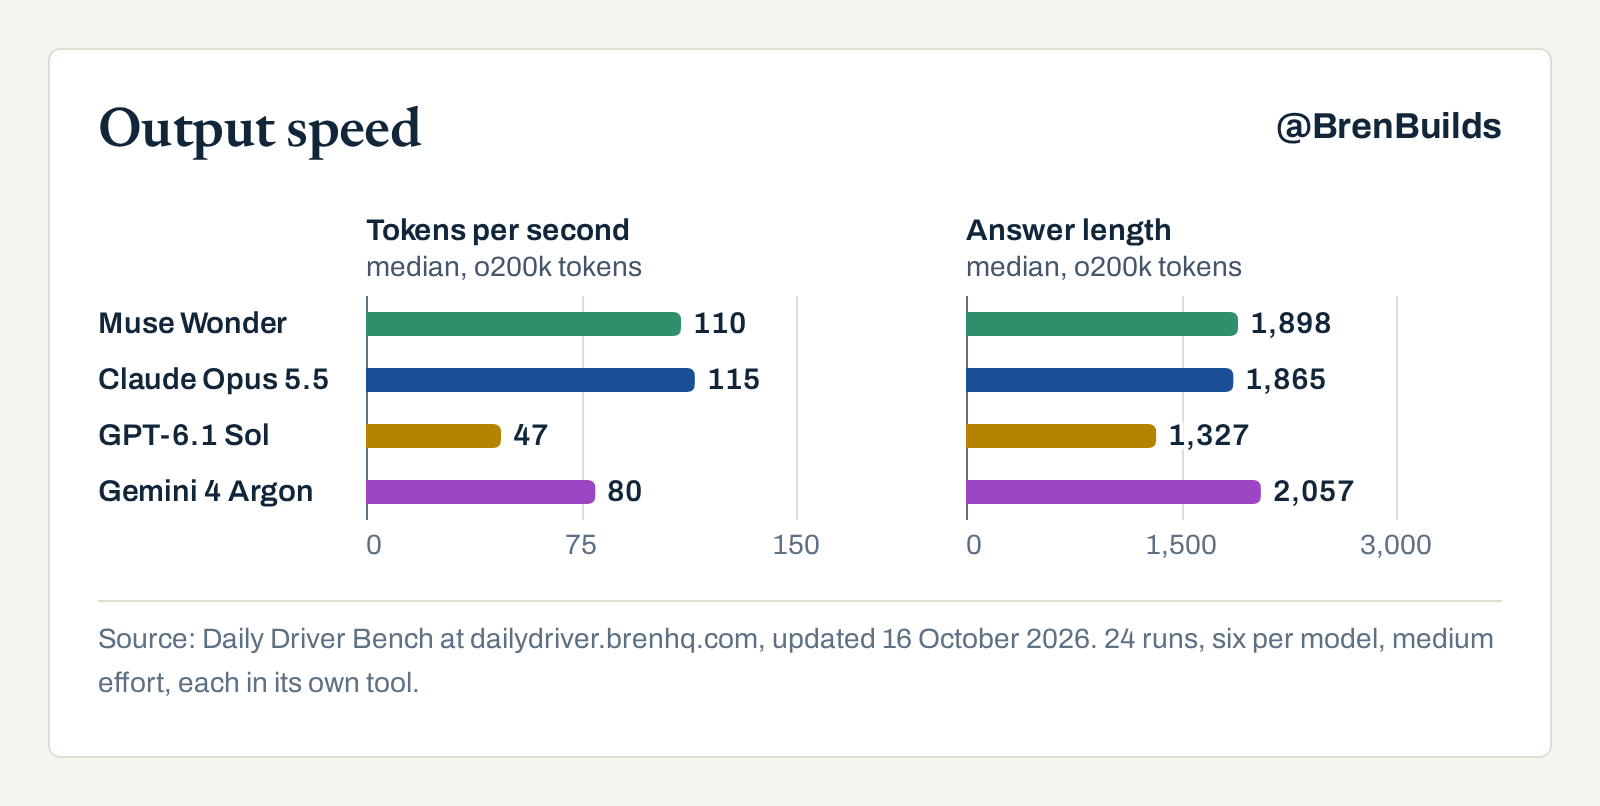
Output speed
Tokens per second while each answer streamed, a walkthrough of at least 600 words. Higher is better.
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 16 October 2026. 24 runs, six per model, medium effort, each in its own tool.
- Muse Wonder: 12.5 to 27.0 s
- Claude Opus 5.5: 11.9 to 19.4 s
- GPT-6.1 Sol: 9.1 to 11.7 s
- Gemini 4 Argon: 16.0 to 129.2 s
Cost#
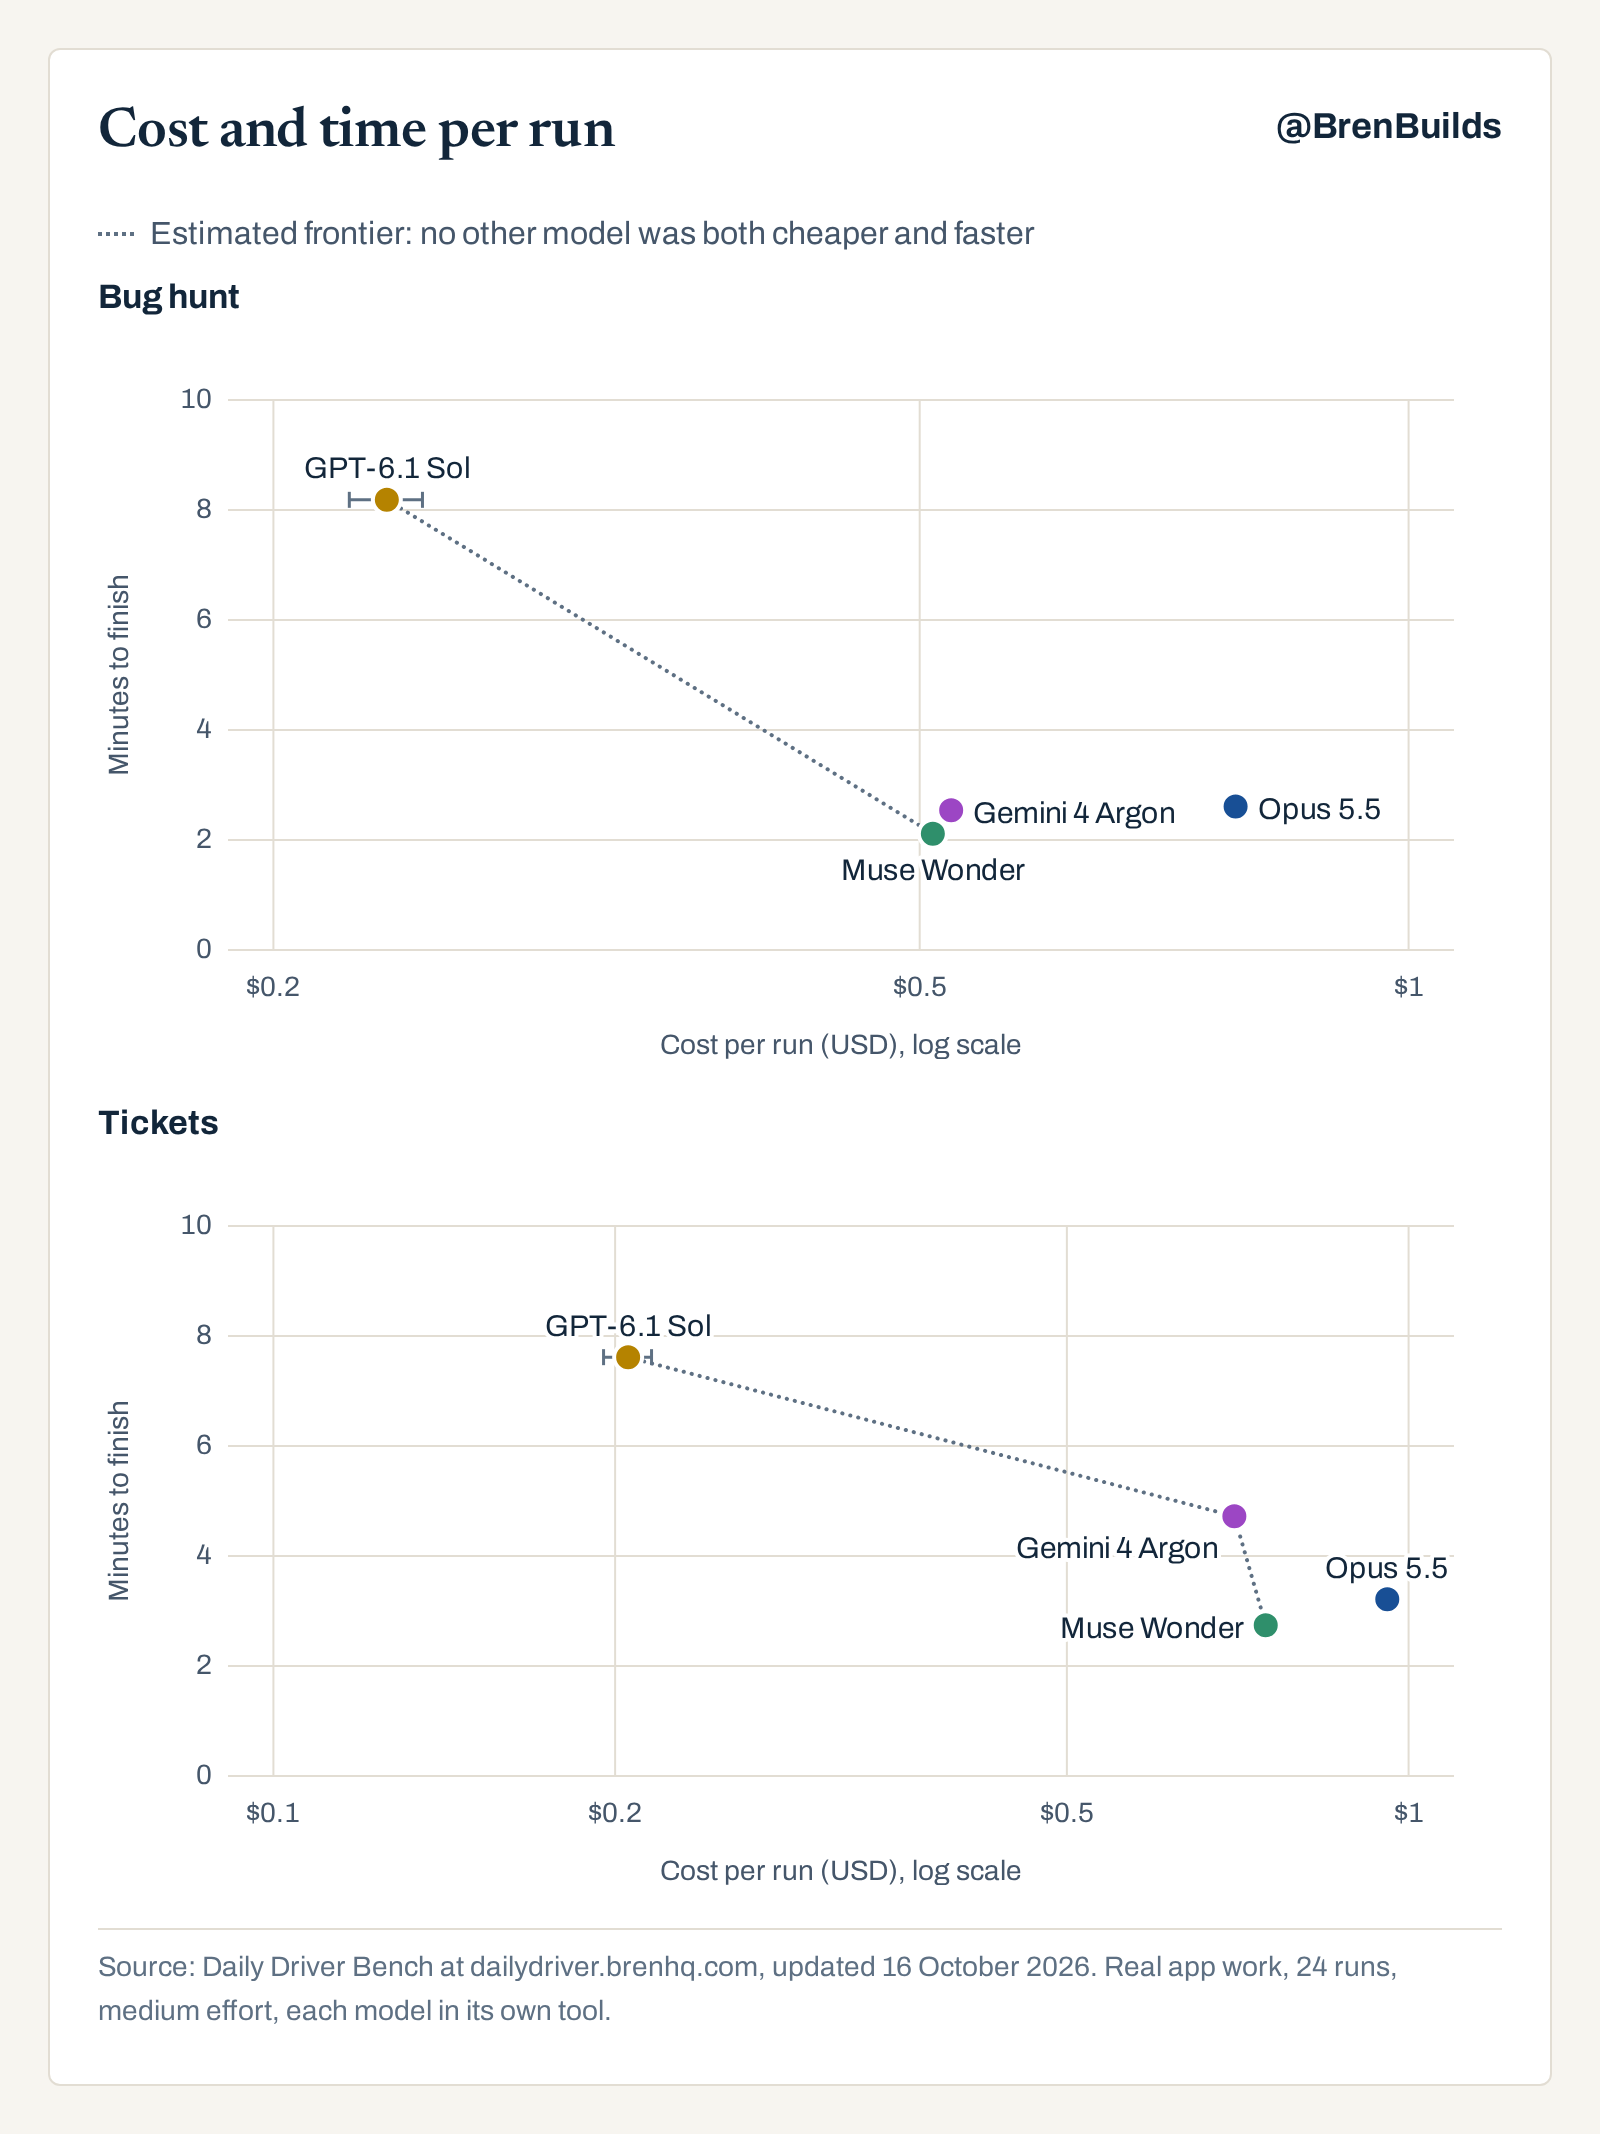
Cost and time per run
Real app work, median run at list prices. All four fixed every bug and passed every ticket test. Lower left is cheaper and faster.
- Estimated frontier: no other model was both cheaper and faster
Bug hunt
Tickets
Source: Daily Driver Bench at dailydriver.brenhq.com, updated 16 October 2026. Real app work, 24 runs, medium effort, each model in its own tool.
Every check#
The same checks for all four.
| Check | Muse Wonder | Claude Opus 5.5 | GPT-6.1 Sol | Gemini 4 Argon |
|---|---|---|---|---|
| Four small coding tasks, every setup: runs that passed | 60 of 60 | 60 of 60 | 60 of 60 | 60 of 60 |
| ASD-STE100 instruction on the explain task: runs that passed | 3 of 3 | 3 of 3 | 3 of 3 | 3 of 3 |
| Bug hunt: bugs fixed of 20, each run | 20, 20, 20 of 20 | 20, 20, 20 of 20 | 20, 20, 20 of 20 | 20, 20, 20 of 20 |
| Bug hunt: runs that edited the existing tests | 0 of 3 | 0 of 3 | 0 of 3 | 1 of 3 |
| Bug hunt: estimated cost per run at list prices, median | $0.51 | $0.78 | $0.22 to $0.25 | $0.52 |
| Tickets: hidden tests passed, each run | 17, 17, 17 of 17 | 17, 17, 17 of 17 | 17, 17, 17 of 17 | 17, 17, 17 of 17 |
| Tickets: estimated cost per run at list prices, median | $0.75 | $0.96 | $0.20 to $0.22 | $0.70 |
The table scrolls sideways on a small screen.
Every run counts. A run that edits an existing test fails, whatever else it fixed. Runs from Muse Wonder 16 October, Claude Opus 5.5 22 to 30 September, GPT-6.1 Sol 29 to 30 September and Gemini 4 Argon 13 October, 2026.
How I ran it#
Background and method
Muse Wonder and Gemini 4 Argon ran in Cursor CLI 2026.10.01-e373342 as Cursor's medium versions, Claude Opus 5.5 in Claude Code 2.1.284 and GPT-6.1 Sol in Codex CLI 0.159.0, all at medium effort. All four ran in Docker on my subscriptions, with no API keys.
Time to finish is the whole run on one short explain task, from starting the tool to its exit, so it includes start-up. A run passes when the answer names the month logic and the ValueError.
Output speed comes from a separate session, a walkthrough of at least 600 words, six runs each. I saved each answer, counted it with OpenAI's o200k tokenizer and divided by the seconds from its first answer token to its last. I timed Claude Code's tokens at a local proxy, Codex's on its WebSocket and Cursor's on its own stream, so buffering can shift the rates. Start-up, reading the file and thinking are left out. OpenAI's own count for Sol's answers is within 0.5% of the o200k count. Anthropic counts Opus 5.5's answers as about 1.4 times as many tokens. A run counts when it passed and streamed in 20 or more pieces, and a median needs three; every run counted.
The checks are four small coding tasks with no skill, a placebo file and three token-saving skills, three runs each; the ASD-STE100 instruction on the explain task; and a bug hunt with 20 planted bugs and three sprint tickets in a small TypeScript app, graded by hidden tests. Opus 5.5, Sol and Argon use their published runs of the same tasks.
Costs are list-price estimates from each run's tokens. Muse Wonder is $4 per million input tokens, $0.20 cached and $20 output, the same as Claude Opus 5.5, and Meta lists no cache-write price. Gemini 4 Argon is $2, $0.10 and $10 until 30 November 2026, then double. Opus 5.5's cost includes cache writes at twice its input price. Muse Wonder and Opus 5.5 have the same list prices. Most of the gap is Opus 5.5's cache writes, 53,000 to 58,000 tokens a run at twice its input price. Cursor reports none for Muse Wonder. Muse Wonder also wrote fewer output tokens, 13,000 to 18,000 a run to Opus 5.5's 16,000 to 21,000. Sol's is a range because Codex logs no cache writes. I paid through subscriptions, not these amounts.
The run records are in results.json, under launch28_timing, launch28_runs and launch28_real_runs, with Gemini 4 Argon's under launch27_runs and launch27_real_runs, and Opus 5.5's and GPT-6.1 Sol's under runs, ste_runs and bughunt_runs.